
Microsoft Ignite 2026: Seven New MAI Models, Maia 200 & Licensed Weights Deep Dive
Microsoft Ignite 2026 · November 17, 2026 · Seven Proprietary Microsoft AI (MAI) Models Quietly Ship to Production
While developers across the industry were watching the benchmark brawl between GPT-6.2, Claude Fable 5.2, and Gemini 4, Microsoft AI (MAI) quietly dropped seven brand-new world-class proprietary models engineered specifically for 24/7 enterprise agent unit economics at Microsoft Ignite 2026 (November 17). The lineup spans cybersecurity defense (MAI Cyber 2 Flash), everyday software engineering (MAI Code 2 / Code 2 Flash), image generation and editing (MAI Image 2.7 / Flash), real-time voice (MAI Realtime 1), clinical transcription (Dragon Copilot Transcribe), and intelligent model routing (Decision 1.1)—all running on Microsoft's now-production second-generation Maia 200 custom silicon (1.7x more tokens per watt) alongside MAI Licensed Weights for private Azure deployment.
MAI Cyber 2 Flash
92.3% · <2% Cost
Beats GPT-6 Astra · 1M Context
MAI Code 2 Daily Coding
96% Opus 5.5 · 5% Price
64% blind frontend preference over 6 Sol
MAI Image 2.7 Editing
AA Global #1 · 1/5 Price
~$35/1k images · Native Transparency
Decision 1.1 & Realtime
79x Cheaper · $0.01/min
Maia 200 delivers 1.7x tokens per watt
 Figure 01: Microsoft AI (MAI) proprietary model lineup unveiled at Ignite 2026, built around matching every workload with the right model that can affordably run 24/7
1. Full Overview: Positioning & Benchmark Ledger for Microsoft Ignite 2026's Seven MAI Models
Microsoft's launch post opens by naming the core anxiety facing enterprise AI teams today: as autonomous agents drive exponential growth in token volume, enterprises do not need ultra-expensive lab trophies—they need top-tier capability priced low enough to run agents 24/7/365 in production. The table below summarizes all seven models (plus the Flash and MAI Work Flash variants) introduced in this wave:
| Model & Track | Core Engineering Role | Benchmarks & Competitive Comparisons | Pricing & Availability |
|---|---|---|---|
| MAI Cyber 2 Flash (Security · 1M Context) | Lightweight frontier security model built for 24/7 repo vulnerability hunting, patch suggestions, and security investigations | 92.3% on deduplicated 813-task CyberGym-E2E beating GPT-6 Astra (91.5%); 40.4% on WebExploitBench beating GPT-5.6 Cyber | $0.10 / $0.01 / $0.50 per 1M input/cached/output tokens (output down 86%, <2% of GPT-6 Astra per-task cost); rolling out automatically across Microsoft security products (including Codename MDASH) from mid-December |
| MAI Code 2 (Daily Engineering Workhorse) | Built for high-frequency enterprise GitHub Copilot workflows: production PRs, deep debugging, multi-file builds, full-repo reasoning, and frontend UI | Averages 98% of GPT-6.1 Sol and 96% of Claude Opus 5.5 across 4 daily coding benchmarks; 64% blind frontend/3D preference over GPT-6 Sol (258 raters) | 40% of GPT-6.1 Sol's price and 5% of Claude Opus 5.5's price (including 50% promo comparison); live now in GitHub Copilot, coming to OpenRouter / Vercel / Hermes / Open Code / Kilo |
| MAI Code 2 Flash (+ Work Flash) (High-Speed Coding & M365) | Tuned for code explanation, targeted edits, routine fixes, and rapid iteration; spawns MAI Work Flash for M365 and Fabric IQ | Matches GPT-6 Luna and Haiku 5.5 on DeepSWE / Terminal Bench 2.1 / SWE-Atlas; cuts Word input tokens by 42% and Teams tool-calling tokens by 28% | 65% of GPT-6 Luna's price and 20% of Claude Haiku 5.5's price; live in GitHub Copilot and limited preview in Microsoft Foundry |
| MAI Image 2.7 (+ Flash) (Generation & Precision Editing) | #1 global image editing and high-speed generation pair supporting detail-locked edits, native transparent backgrounds, and interactive Canvas | #1 globally on AA-Image-Editing v2.1 (1,215 Elo, 5,478 votes); #4 in AA generation behind two top labs; top-2 lab on Arena text-to-image & editing | Image 2.7 ~$35/1k images (1/5 of GPT Image 2.6 Sunburst max); Flash ~$10/1k; free to try on MAI Labs (+ Canvas), public preview on Foundry, plus fal / Genspark / OpenRouter |
| MAI Realtime 1 (Real-Time End-to-End Voice) | Microsoft's first native Speech-to-Speech model featuring interruption handling, dual-speed reasoning, noise robustness, and enterprise tool use | Outperforms GPT-Realtime 2.1 on Big Bench Audio and τ-Voice agent completion; 100% compatible with OpenAI Realtime API | Base voice from $0.01/min (optional deep reasoning at $1/$5 per 1M input/output tokens); try now on MAI Labs, limited preview on Foundry (coming to Dynamics 365 Contact Center) |
| Dragon Copilot Transcribe (MAI-Transcribe-2) (Clinical Transcription) | World's fastest, highest-accuracy multilingual speech transcription model for dense jargon, code-switching, and near-zero tolerance environments | Handles 100% of doctor-patient transcription in Dragon Copilot across 10M monthly visits while cutting multilingual word error rates in half | Enterprise scale pricing; already deployed in clinical production across 1/3 of practicing U.S. physicians and fully integrated into Microsoft Dragon Copilot |
| Decision 1.1 (Intelligent Model Router) | Low-latency application-embedded router keeping routine/high-frequency requests on small models and escalating to frontier tiers only when needed | Outperforms Jev, Google, and OpenAI on the AA Decision Index; already deployed by 4,000 enterprise customers | 50x faster and 79x cheaper than GPT-6.1 Sol inference; generally available now in Microsoft Foundry (GA: aka.ms/decision-model-ga) |
2. Track-by-Track Breakdown: Security, Coding, Imagery & Speech
2.1 MAI Cyber 2 Flash: 92.3% Vulnerability Defense Beating GPT-6 Astra at Under 2% Per-Task Cost
Microsoft argues that in 2027 and beyond, Security, Alignment, and Containment supersede everything else: when attackers wield vast fleets of cheap automated exploit tools, defenders must run security audit and patching agents continuously 24/7 across production codebases. Backed by decades of first-party threat intelligence and security engineering data, MAI Cyber 2 Flash delivers both rare benchmark rigor and drastic cost compression:
- Strict Decontaminated Benchmark Validation: When auditing the 905-task CyberGym-E2E suite, Microsoft discovered that 92 tasks overlapped with open-source repos or public vulnerability reports present in training data (even though ground-truth patches were never used). To keep the evaluation spotless, Microsoft excluded those 92 tasks across every evaluated model and reported solely on the remaining 813 clean tasks: using half the reasoning budget, MAI Cyber 2 Flash scored
92.3%, beatingGPT-6 Astra's91.5%, and at matched reasoning budgets scored40.4%onWebExploitBenchvs.GPT-5.6 Cyber's38.4%. - Per-Task Cost Cut Under
< 2%: Listed at just$0.10(input) /$0.01(cached read) /$0.50(output) per million tokens—an 86% output price cut compared with MAI Cyber 1.1 Flash. Against Azure OpenAI GlobalGPT-6 Astra($10 / $1 / $50), completing a real-world vulnerability task costs less than 2% as much. - 1M Token Context + Production Deployment: With 4x the context window of 1.1 Flash, it ingests massive monorepos and multi-hop call graphs in one pass. MAI Cyber already handles nearly 40% of Codename MDASH security scans (with 90% of adopting customers sticking with it), delivers 20% higher token efficiency than the GPT 5.4 / 5.3 Codex / 5.4 Mini family in Insight Enterprises testing, and rolls out automatically across Microsoft security products starting mid-December.
 Figure 02: MAI Cyber 2 Flash ($0.10 / $0.01 / $0.50) scoring 92.3% on the deduplicated 813-task CyberGym-E2E suite with half the reasoning budget at under 2% of GPT-6 Astra's per-task cost
2.2 MAI Code 2 & Code 2 Flash (Plus MAI Work Flash): Purpose-Built for High-Frequency Enterprise Coding & M365
Microsoft's product team draws an unusually candid boundary: the MAI Code 2 family deliberately ignores pure scientific discovery or open-ended autonomous research, channeling 100% of its compute into the high-frequency tasks enterprise developers run inside GitHub Copilot every day (production pull requests, deep debugging, multi-file implementations, full-repo reasoning, and UI/dashboard builds):
- MAI Code 2 (Daily Full-Stack Workhorse): Across four daily coding benchmarks—DeepSWE 1.1, Terminal Bench 2.1, SWE-Atlas, and FrontierCode v1.1 (with the first three evaluated on MSBench via sub-agent-free GitHub Copilot CLI and MAI pricing reflecting its 50% promo tier)—it averages 98% of
GPT-6.1 Sol's performance at 40% of the cost, and 96% ofClaude Opus 5.5's performance at just 5% of the cost. Even more surprising is frontend taste: across a 258-rater blind evaluation covering UI, games, data visualization, 3D scenes, and SVGs, developers preferred MAI Code 2 overGPT-6 Sol64% of the time. Now live in GitHub Copilot, with OpenRouter, Vercel, Hermes, Open Code, and Kilo integrations following shortly. - MAI Code 2 Flash (High-Speed Routine Edits): Built for code explanation, targeted patches, bug fixes, and rapid iteration, matching
GPT-6 Luna(at 65% of the price) andClaude Haiku 5.5(at 20% of the price), available in GitHub Copilot and limited preview on Microsoft Foundry. - The Unsung Workhorse — MAI Work Flash: Distilled from Code 2 Flash specifically for office productivity and BI workloads across M365 and Fabric IQ—saving ~42% input tokens per call in Word while matching larger GPT-6.1 Sol, cutting Teams decision-tracking and tool-calling tokens by up to 28% while outperforming GPT-6 Luna, and beating
GPT-5.6-sol,GPT-6-astra, andOpus-5.5on Fabric IQ DAX query generation powering Power BI's "Chat with your Data."
 Figure 03: MAI Code 2 achieving 98% of GPT-6.1 Sol at 40% price, 96% of Claude Opus 5.5 at 5% price, and a 64% blind frontend preference rate
2.3 MAI Image 2.7 & Flash: #1 Global Image Editing Model + Native Transparency + Interactive Canvas
Powering Bing Image Creator as its default engine since Build in June (driving ~14.7% compound weekly growth in usage), MAI Image 2.7 reached #1 globally on Artificial Analysis Image Editing v2.1 as of November 16, 2026 (1,215 Elo across 5,478 votes—4 Elo ahead of GPT Image 2.6 Sunburst max at one-fifth the price). On Arena, it also beat GPT Image 2.6 Flare in both text-to-image and single-image editing, cementing Microsoft as a top-two global imaging lab.
- Ultra-Accessible Enterprise Unit Pricing: Microsoft Foundry public preview lists
MAI Image 2.7at ~$35 per 1,000 images (~$0.035/image) and high-speedMAI Image 2.7 Flashat ~$10 per 1,000 images (one cent per commercial asset). - Three Essential Capabilities for E-Commerce & Design Studios: ① Consistent multi-turn fine-grained editing (changing product color, material, or placement without distorting surrounding text, lighting, or perspective); ② Native transparent background output on both models, eliminating manual cutout steps for SKUs, logos, and icons; ③ Interactive
Canvaspowered by 2.7 Flash on MAI Labs, turning rough sketches into polished diagrams with selective region repainting and repositioning. - Partner Ecosystem Adoption: Adopted by Adobe, Figma Weave, Sports Illustrated (Minute), Wirestock, and Manus, and accessible via MAI Labs, Microsoft Foundry, fal, Genspark, and OpenRouter.
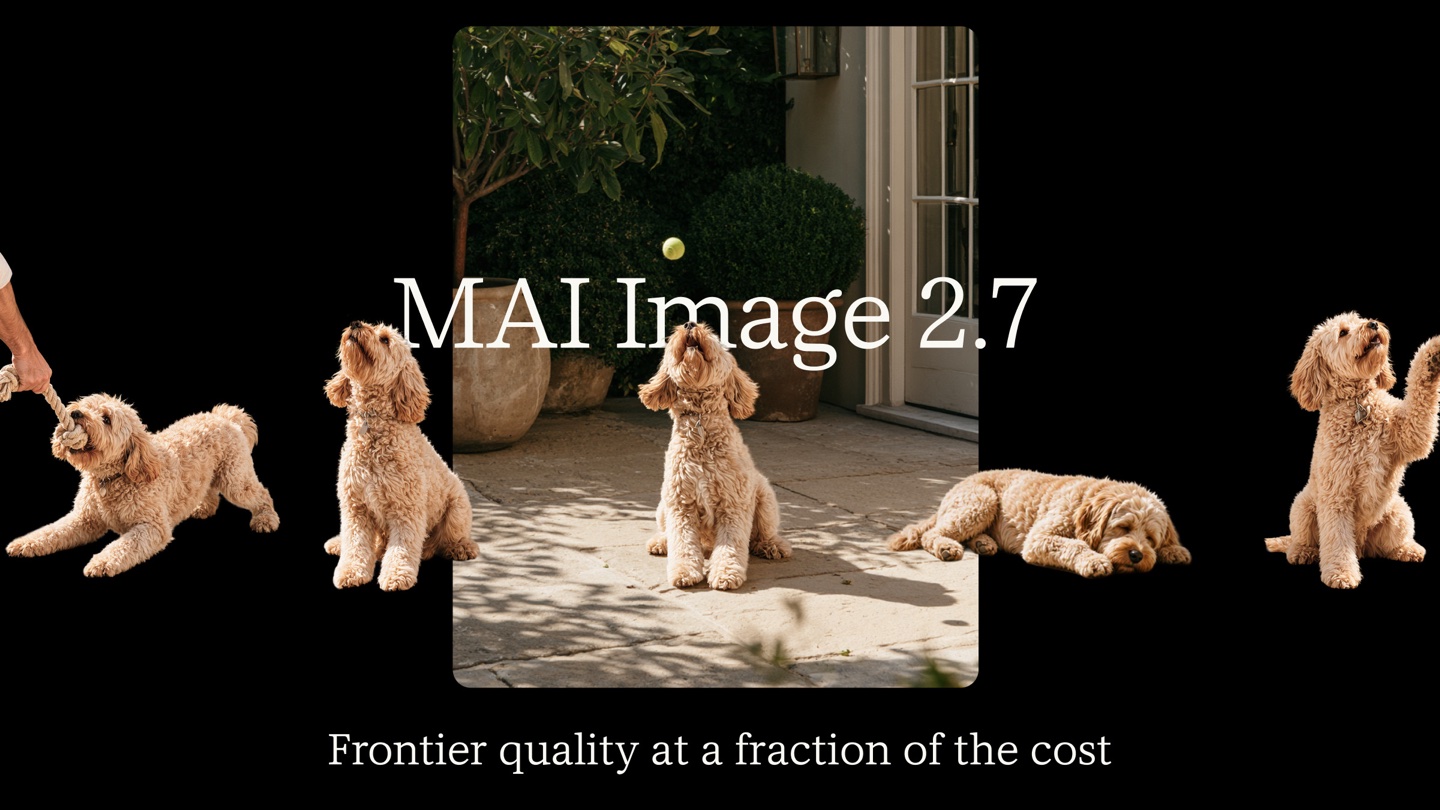 Figure 04: MAI Image 2.7 ranked #1 globally on AA Image Editing ($35/1k) alongside $10/1k Flash, both supporting native transparent backgrounds
2.4 MAI Realtime 1 ($0.01/min Real-Time Voice) & MAI Transcribe 2 (Clinical-Grade High-Speed Transcription)
MAI Realtime 1 is Microsoft's first native Speech-to-Speech conversational model, outperforming GPT-Realtime 2.1 on both Big Bench Audio voice reasoning and τ-Voice agent task completion:
- Aggressive Pricing & Zero-Friction Protocol Migration: Base real-time conversation starts at
$0.01per audio minute, with complex deep-reasoning turns billed separately at$1 / $5per million input/output tokens. Crucially, it is 100% compatible with theOpenAI Realtime API, allowing existing teams to drop it in and benchmark with almost zero protocol changes (already tested by Agoda, Reservations.ai, Dynamics 365 Contact Center, and nurse clinical training simulators). - Five Capabilities Built for Complex Voice Agents: Natural barge-in and low-latency turn-taking; adaptive dual-speed reasoning (streaming effortlessly for casual banter while seamlessly invoking deeper reasoning on hard questions without awkward dead air); background noise and multi-speaker cross-talk resilience; direct enterprise tool execution; and prompt-driven persona switching.
- Dragon Copilot Transcribe (MAI-Transcribe-2): The world's fastest and most accurate multilingual transcription engine, handling 100% of real-time clinical transcription across 10 million patient visits per month, cutting multilingual error rates in half, and serving one-third of practicing physicians across the U.S.
 Figure 05: MAI Realtime 1 delivering $0.01/min enterprise real-time voice interaction with full OpenAI Realtime API protocol compatibility
3. Decision 1.1 Routing, Second-Gen Maia 200 Silicon & MAI Licensed Weights
What allows this seven-model portfolio to break through enterprise cost floors is Microsoft's three-layer infrastructure stack spanning silicon, routing, and private weight governance:
- Decision 1.1 Intelligent Router (GA)
50x Faster & 79x Cheaper Than GPT-6.1 Sol
Outperforms Jev, Google, and OpenAI on the AA Decision Index. Embedded directly inside applications so simple high-frequency traffic never wastes frontier compute—already adopted by 4,000 enterprise customers and generally available in Foundry.
- Second-Gen Maia 200 Custom Silicon in Production
1.7x More Tokens per Watt
Microsoft's second-generation custom AI accelerator Maia 200 is now in full production running MAI's largest inference workloads, locking in a structural energy-efficiency moat at the data center layer.
- MAI Licensed Weights
Your IQ. Your Agents. Your Weights.
Enterprises neither want to feed proprietary business intelligence into external models nor bet core IP on opaque open weights—MAI lets companies deploy frontier checkpoints inside their own Azure tenants with full control over fine-tuning, access, and upgrade cadence.
Enterprise Custom Deployment Case Studies: AT&T (50x Cheaper), Woven by Toyota & Alaska Airlines
- AT&T (5G Network Operations Analytics): Built proprietary network analytics models on customized
MAI Code 2 FlashandCode 2, beatingGPT-6.1 Solat1/50ththe cost on standard 5G operational tasks while cutting complex-scenario costs dramatically at frontier quality. - Woven by Toyota (Automotive Software Engineering): Fine-tuned
MAI Code 2 Flashon historical MISRA automotive safety coding standards; on hard defects that previously forced frontier models to escalate to human engineers, it produced ready-to-merge fixes in44%of cases at less than one-tenth the cost. - Alaska Airlines (Aircraft Maintenance Triage): Fine-tuned
MAI Code 2 Flashto classify aircraft maintenance reports, lifting accuracy from81.2%to91.1%(while strictly preserving final sign-off by certified technicians), outperforming general frontier models at a fraction of the cost.
 Figure 06: MAI Licensed Weights bringing frontier checkpoints directly into customer-owned Azure environments—50x cheaper at AT&T, 44% ready-to-merge MISRA fixes at Woven by Toyota, and 91.1% accuracy at Alaska Airlines
4. Interactive Model Selector & Engineering Recipes: Five Production Agent Blueprints Ready to Deploy
Strategic Takeaway for Solo Builders & Global Teams
Even though Ignite 2026 flew under mainstream social-media radar, its signal to the industry is unmistakable: LLM competition has moved decisively past "single-leaderboard IQ chasing" toward Pareto-frontier unit economics × domain specialization × privately controlled weights. Whether you run CI/CD teams needing affordable unlimited PR security sweeps, cross-border e-commerce teams producing transparent SKU assets at $10–$35 per thousand images, or support engineers shipping $0.01/min 24/7 voice agents, you can validate the entire stack at near-zero cost today via GitHub Copilot, Microsoft Foundry, MAI Labs (Canvas / Realtime 1), and OpenRouter.
Found this actionable? Copy standard citation & summary
Formatted with canonical attribution link and executive summary—ready for Slack, Notion, or LLM context.
Put Into Practice: Companion Browser Workbenches
Side-by-Side Document & Prompt Diff Tool
Compare PDF reports, system prompts, and localized copy side by side with zero uploads.
One IP · Purity & AI Node Telemetry
Inspect residential vs. datacenter ASN, fraud risk score, and AI service routing reachability.