Alibaba Qwen Open-Sources Qwen-Image-2.1: Unified Generation & Native Transparency
Qwen-Image-2.1 breaks open-source bottlenecks: a compact 7B visual backbone, native transparent layer synthesis, up to 10 reference images in a single coherent scene, and mixed-granularity attention with KV cache reuse.
1. Why Qwen-Image-2.1 is the Brightest Star
For a long time, the open-source diffusion community faced a dilemma: chasing photorealism meant ballooning parameter counts that crippled consumer hardware, while practical design needs—clean cutouts, multi-reference coherence, and precise local edits—remained brittle.
The Alibaba Qwen team introduces **Qwen-Image-2.1**, unifying text-to-image synthesis and granular layer editing inside a single framework with only **32 Single-Stream DiT layers and 7B parameters** in its visual backbone.
32-layer Single-Stream DiT with mixed-granularity attention and KV cache reuse across multi-turn prompts.
Direct RGBA synthesis. In-layer text editing, expression updates, and photo subject extraction without clipping artifacts.
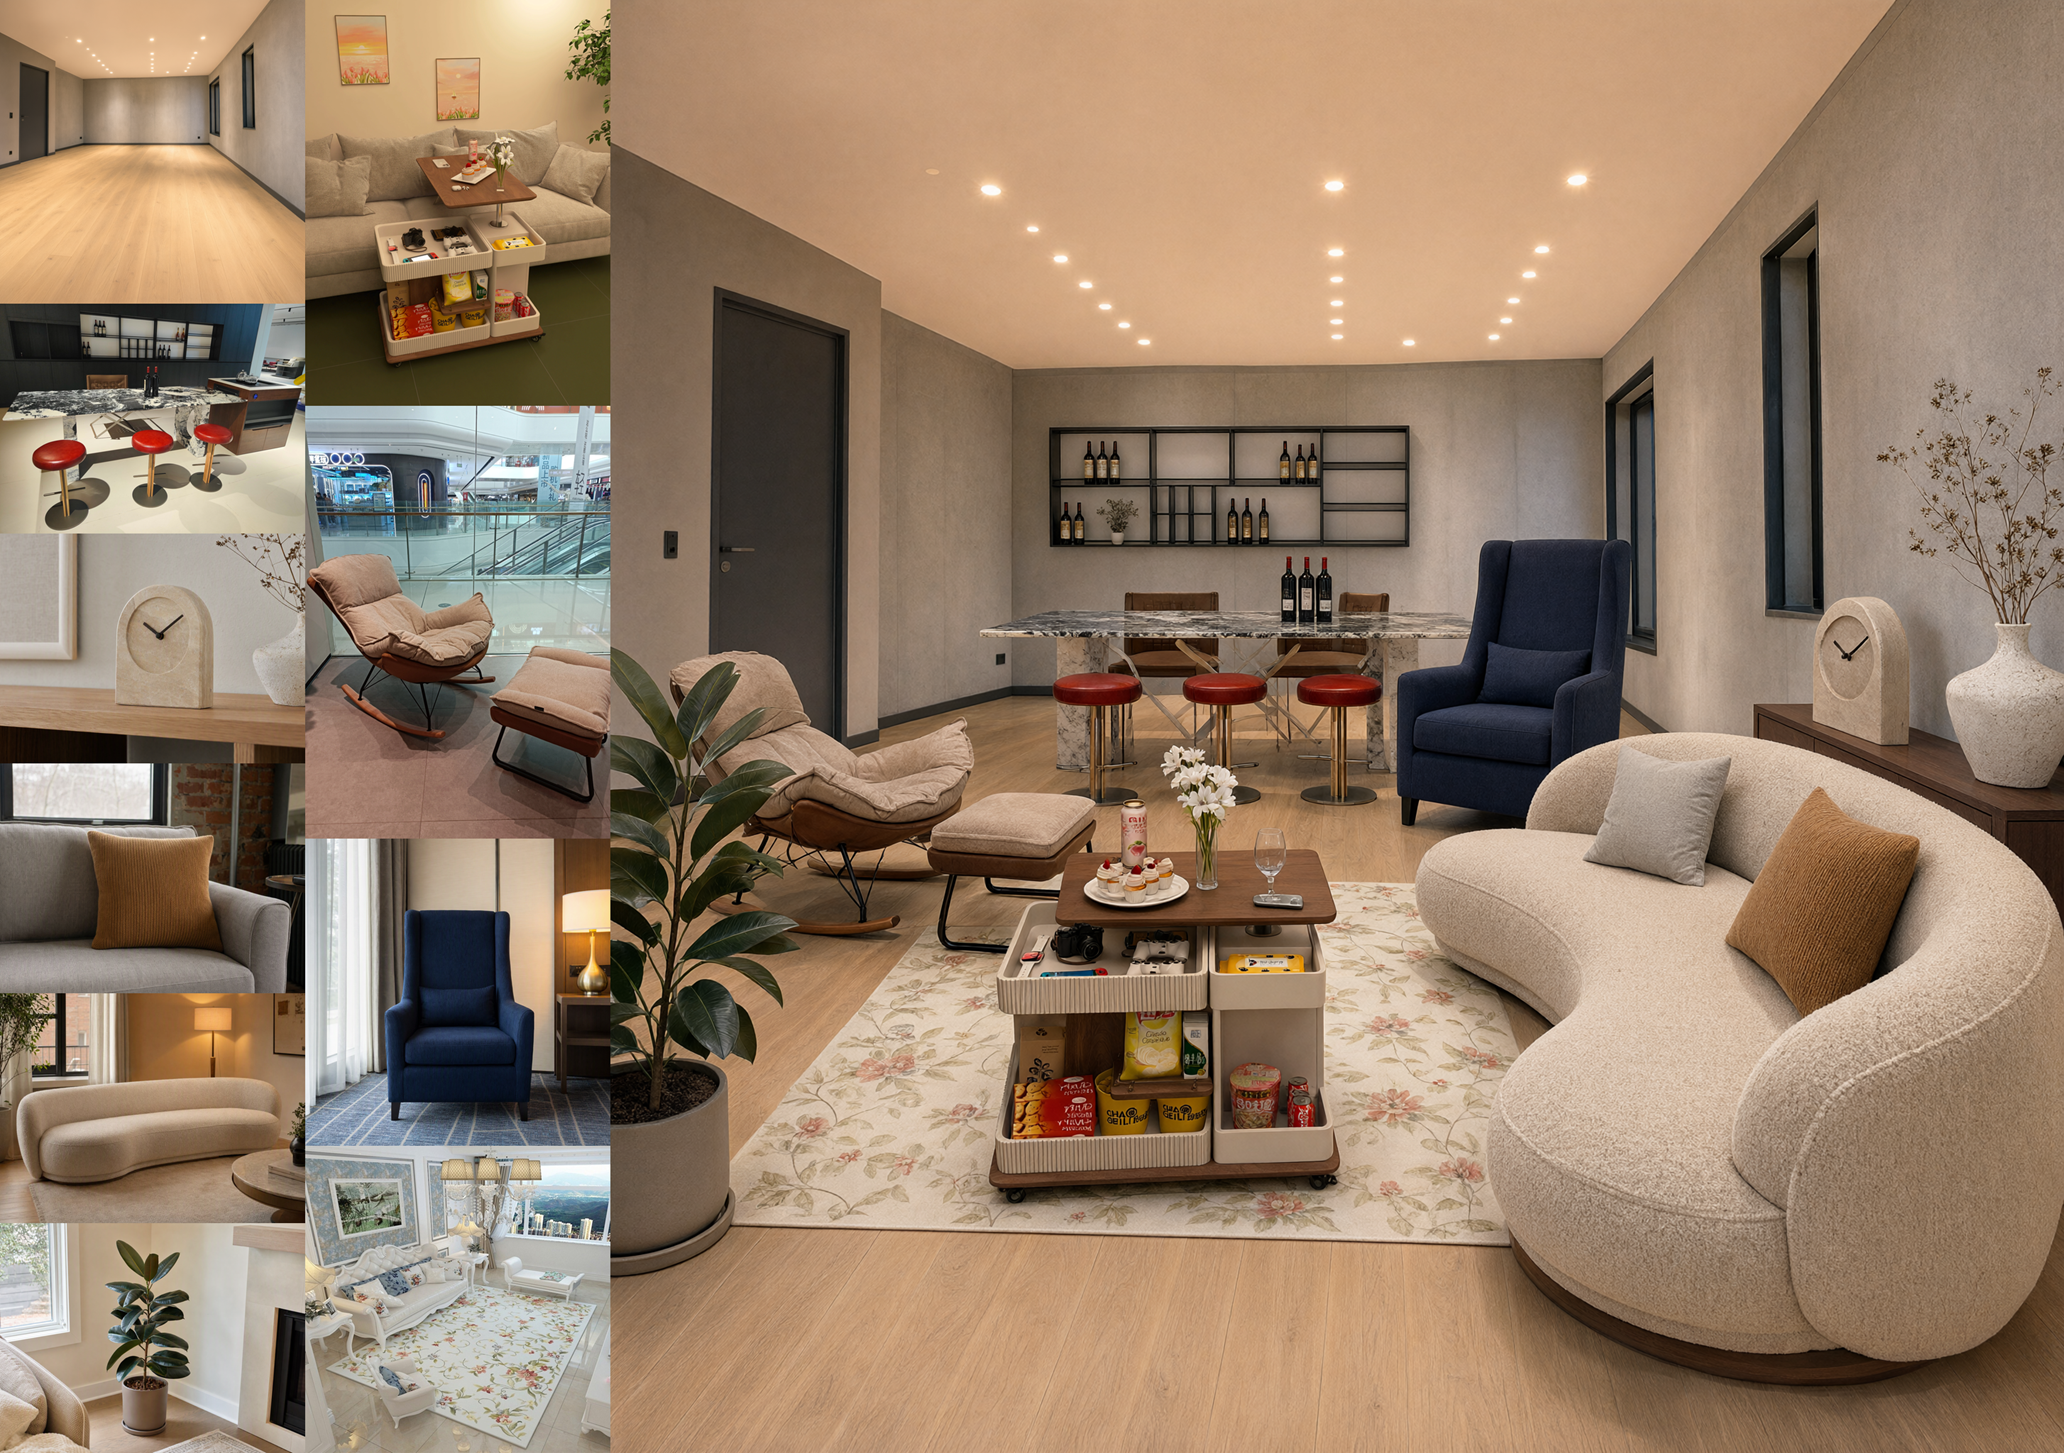
Synthesizes 10 furniture items into cohesive rooms, 5-piece virtual try-ons, and 6-person group portraits with multi-colored visual prompts.
Natural subsurface skin scattering, authentic pores, and flawless typographic kerning for complex posters and labels.
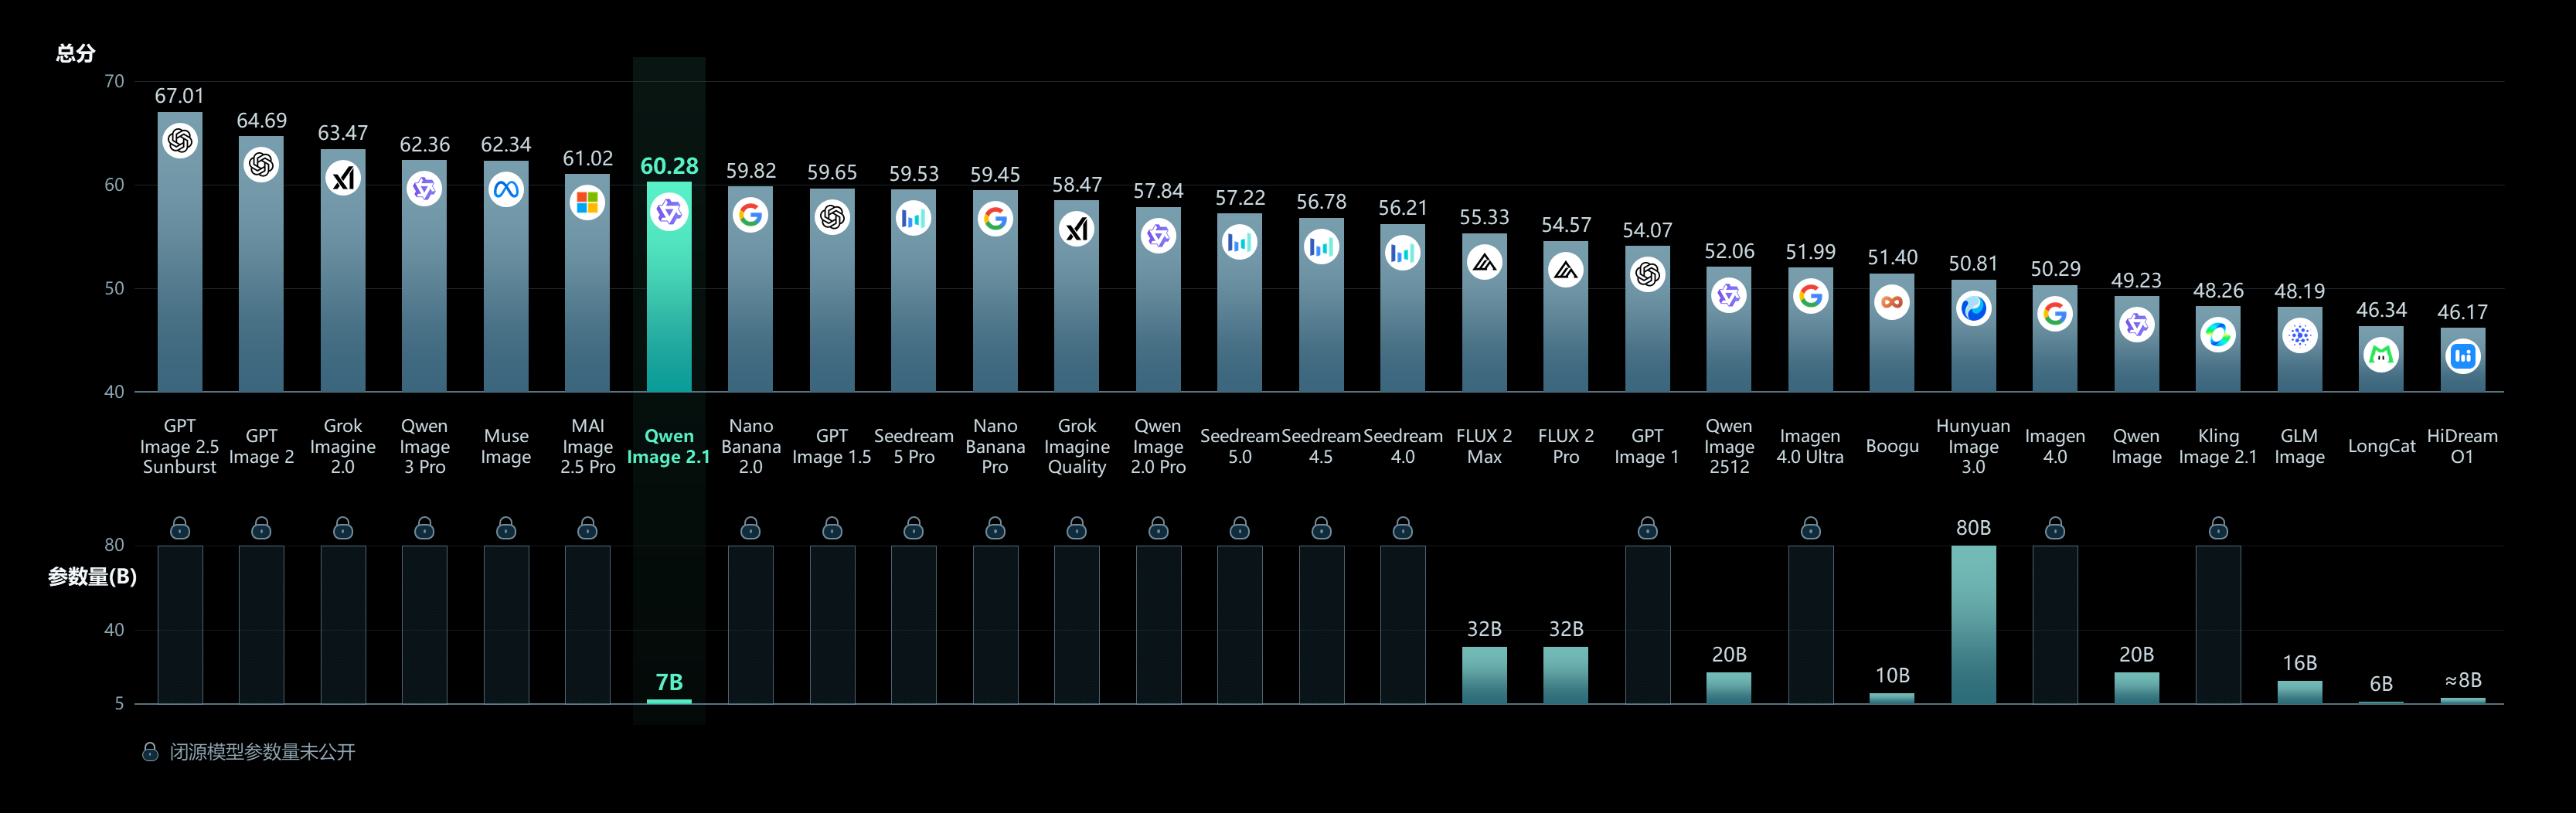
▲ Qwen-Image-Bench 综合评测成绩单:7B 参数在排版、一致性与美学质感上与闭源旗舰模型分庭抗礼
2. Deep Dive: 32-Layer DiT & Mixed-Granularity Attention
How does Qwen-Image-2.1 achieve top-tier fidelity and rapid multi-image editing with only 7B parameters? The breakthrough lies in its **Mixed-Granularity Attention Architecture** and **KV Cache Static Context Reuse**.
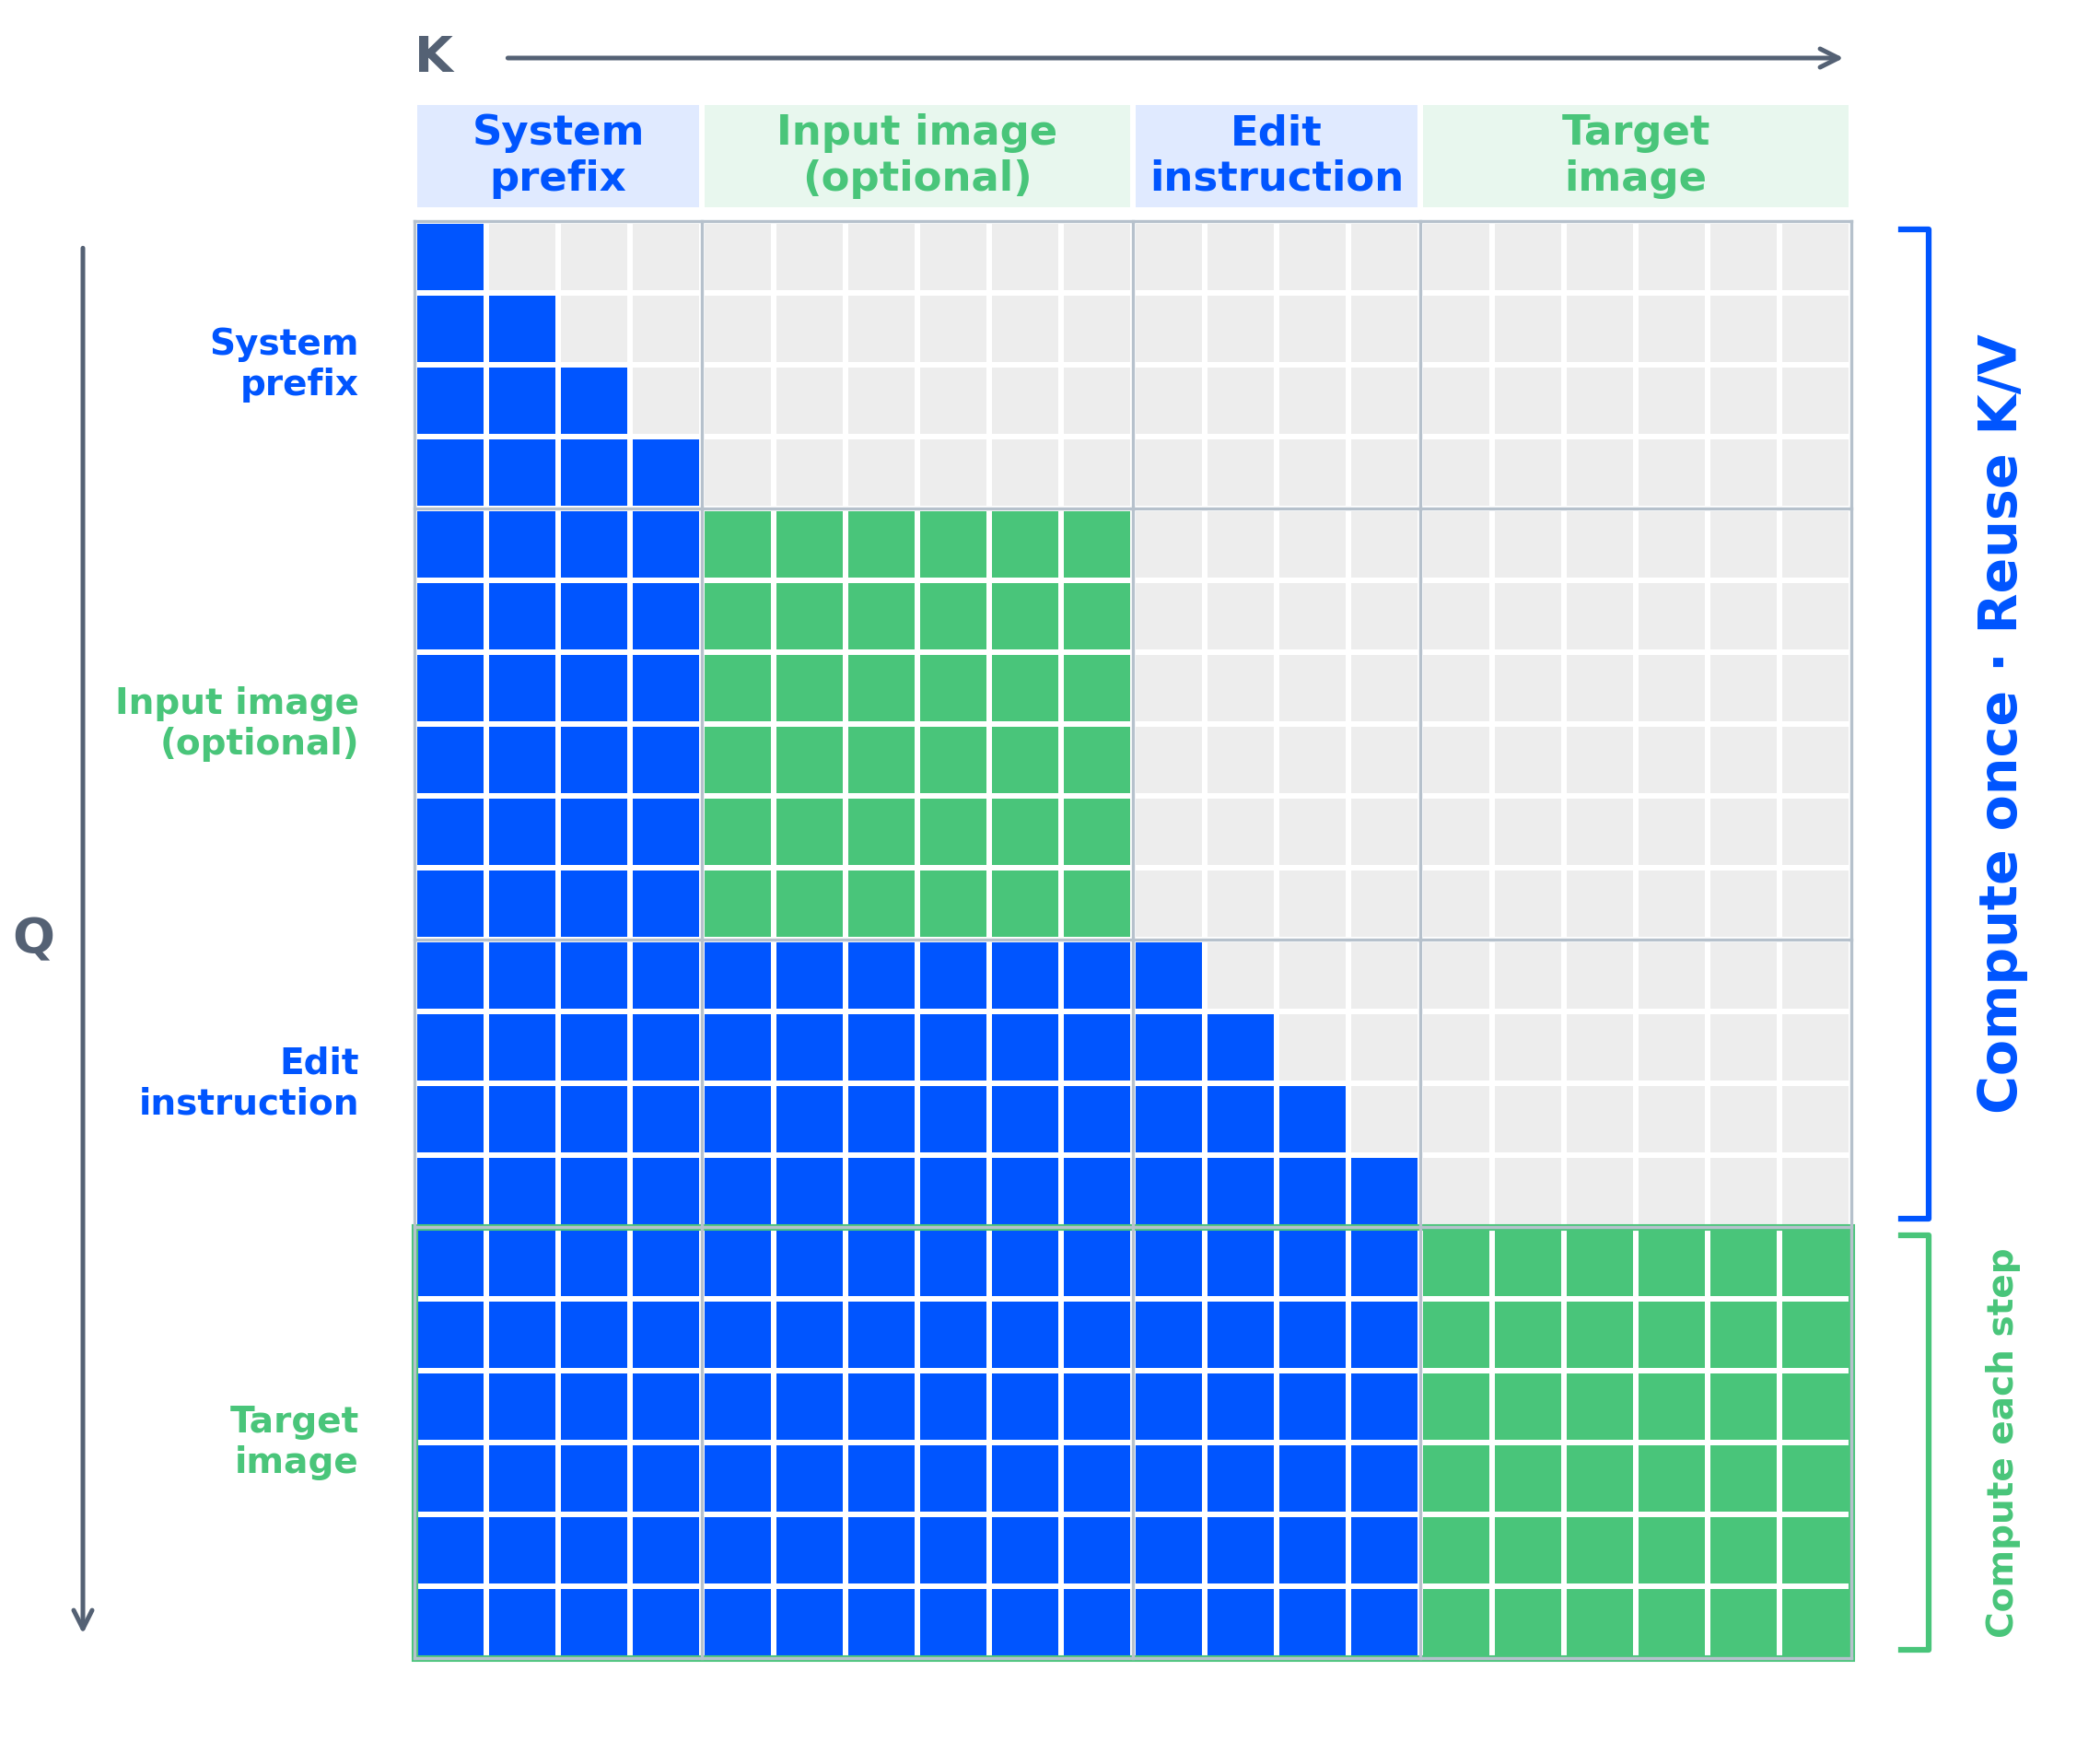
▲ Qwen-Image-2.1 混合粒度注意力机制图解:Token 级掩码 + Chunk 级图像掩码 + 静态上下文预缓存
Text and edit instructions utilize token-level causal masks for strict semantic comprehension, while image latents leverage chunk-level masks for spatial harmony.
Multi-image reference inputs are treated as static context. Their KV activations are computed once in step 1 and cached, slashing subsequent diffusion latency by over 40%.
3. Native Transparency (RGBA): Zero-Fringe Layer Revolution
In Dec 2025, the team released Qwen-Image-Layered. With 2.1, this capability is fully integrated into the unified foundation model. The prompt naturally guides whether to output RGB or direct Alpha transparency.
Native Transparency (RGBA) Real-time Inspector
Switch canvas backgrounds to inspect zero-fringe alpha masking and translucent refraction in direct RGBA output.
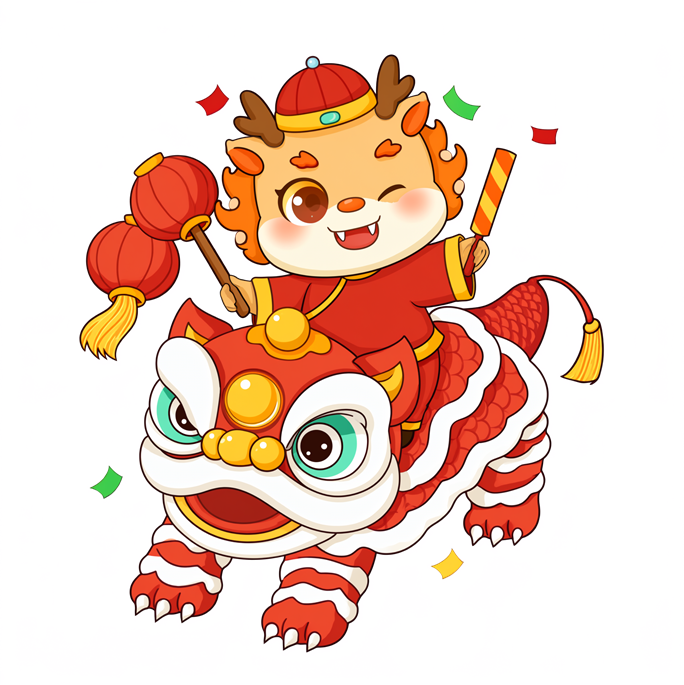
Text-to-Transparent: Crystal Dragon
Directly synthesized with an Alpha channel. Iridescent translucent wings with no fringe or edge artifacts, impossible with classical post-cutout tools.
A mythical crystalline wyvern dragon with translucent iridescent wings, hovering mid-air, emitting subtle bioluminescence, pure alpha transparency background, extremely sharp edges without fringe, ultra photorealistic, 8k resolution, cinematic lighting.
4. Precision Inpainting: Circles, Brushes & Clean Masks
Traditional inpainting accepts a single blurry mask. Qwen-Image-2.1 introduces visual prompting: annotate regions with multiple distinct color circles, paint brushes, or provide an isolated binary mask.
Interactive Split-Slider: Local Inpainting Precision
Drag the split divider horizontally to evaluate inpainting precision across circles, brushes, and binary masks.
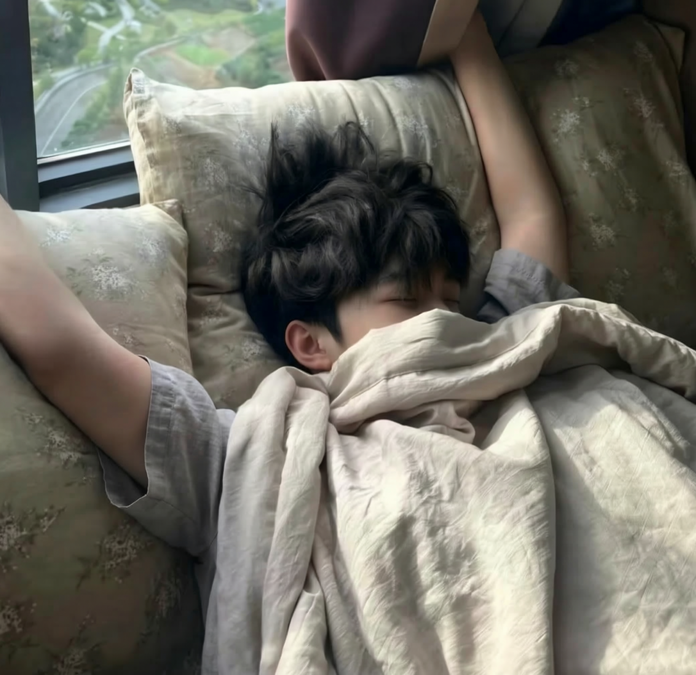
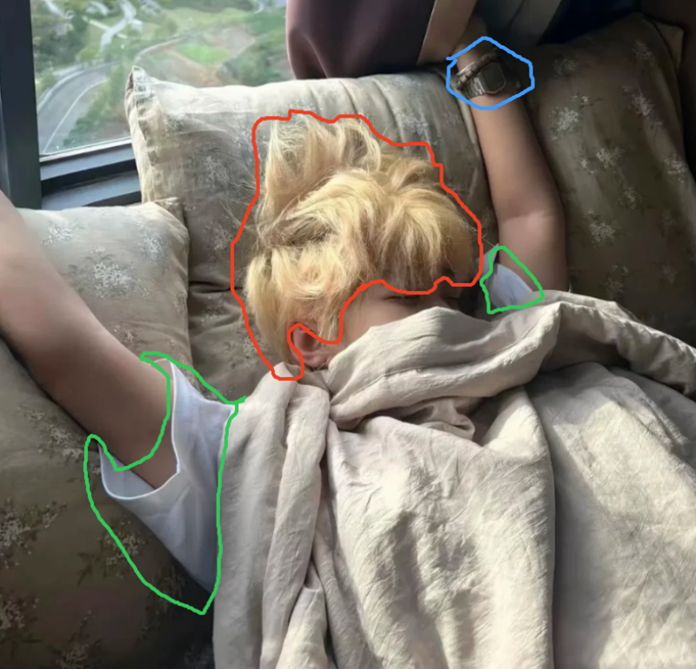
Instruction: Remove metal watch in blue circle, change hair in red circle to black, replace area in green circle with gray linen pajamas.
Single-step inference accurately resolves 3 separate colored areas with distinct additive/subtractive instructions.
5. Up to 10 References: Interior, Try-On & Group Shots
Real-world commercial pipelines struggle with multi-asset collage: combining a model face with apparel often produces harsh seams. Qwen-Image-2.1 unifies up to 10 asset images under consistent physical illumination.
Multi-Reference Spatial Studio (Up to 10 Inputs)
Pushing past legacy 1~2 image limits: explore cohesive 10-piece interiors, virtual try-ons, and group portraits.
6. 360° VR Panoramas, Infographics & Storyboards
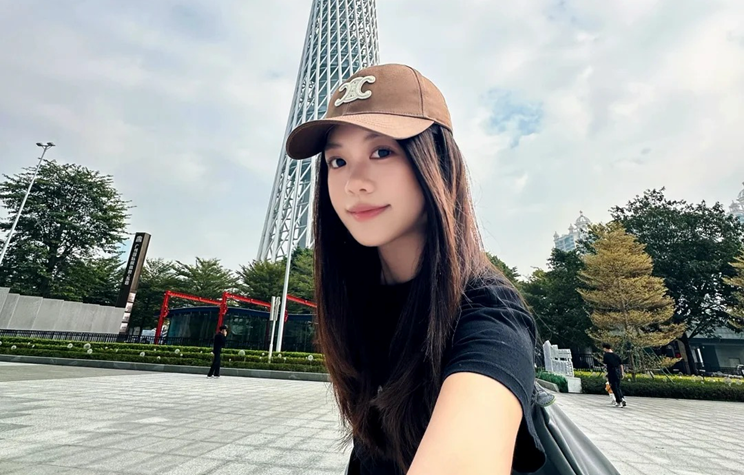
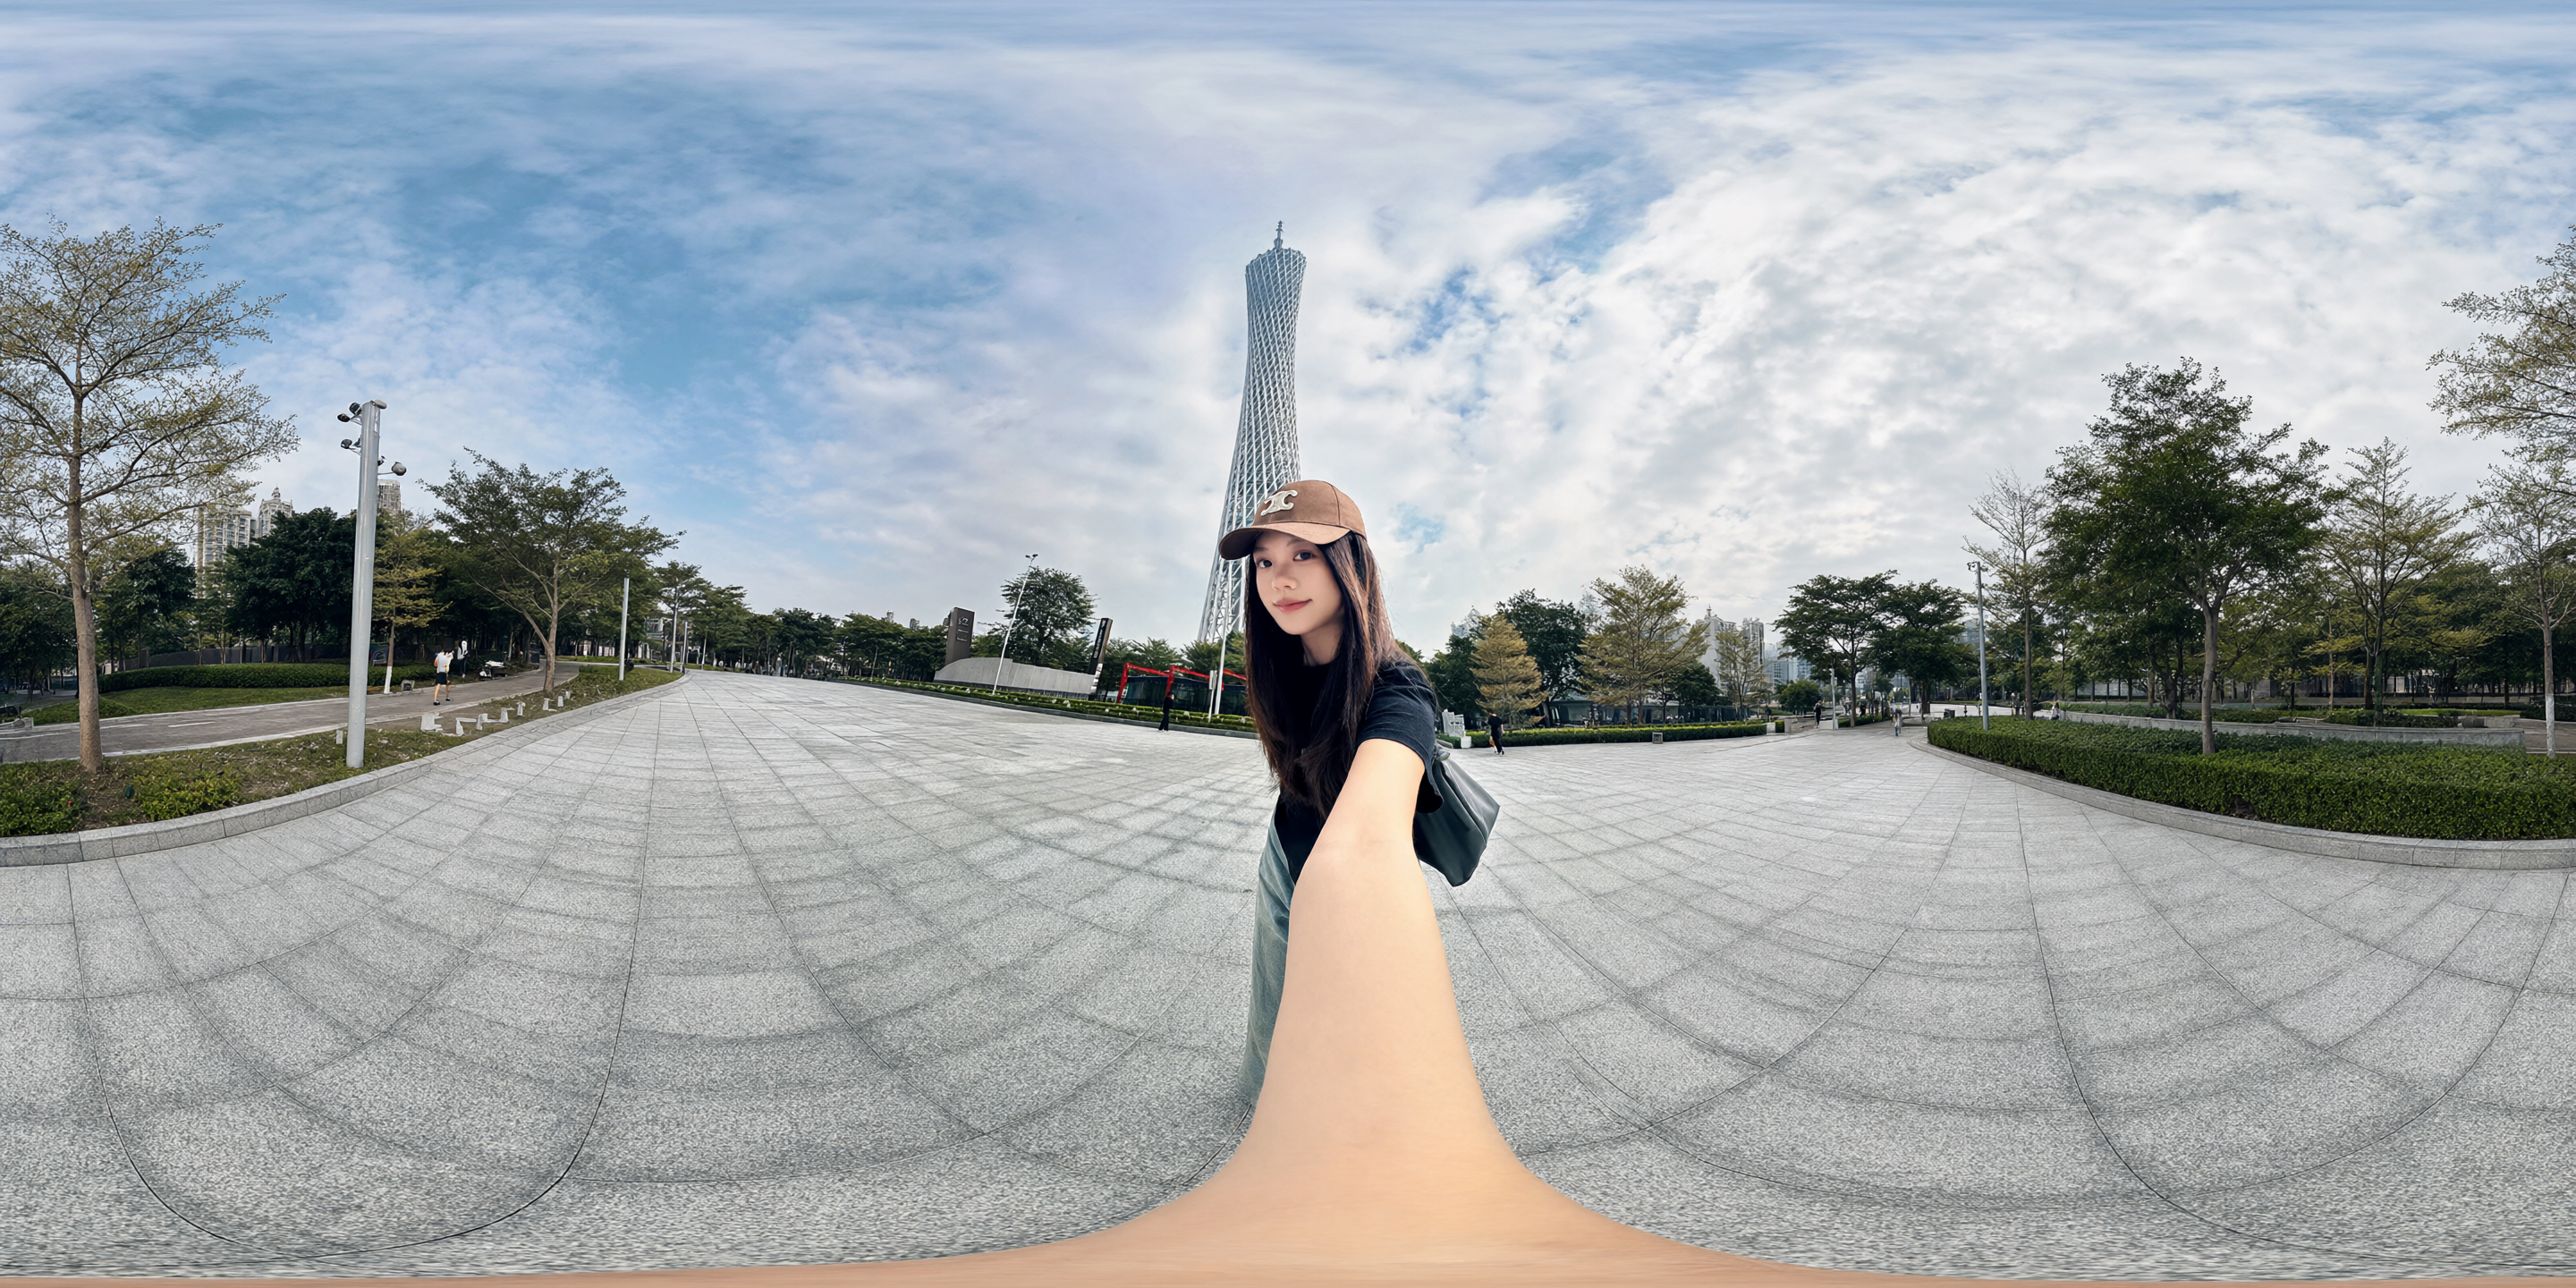
From a single selfie, Qwen-Image-2.1 extrapolates an entire 360° VR environment. From a character turnaround model sheet, it generates a complete 9-panel cinematic storyboard.
Full-Spectrum Tasks: Panorama, Infographics & Storyboards
Expanding beyond static frames: 360° VR panoramas, complex infographics, and multi-frame narratives.
7. Complete 48-Image Sample Vault & Prompts
Explore all generation showcases from the official benchmark. Click any image to view in a full-screen Lightbox, and click the Prompt button to copy.
Complete 48-Image Sample Vault & Prompt Treasury
Explore the full spectrum of official samples with prompt copying and full-size lightbox preview.
Qwen-Image-Bench Benchmark
Comprehensive evaluation across typography, alignment, and aesthetics.
Mixed-Granularity Attention Architecture
Token-level causal mask + chunk-level mask + KV cache reuse.
Native Transparency: Iridescent Crystal Dragon
Direct Alpha generation
Native Transparency: Mechanical Heart
Clean transparency through intricate cogs
Native Transparency: Water Creature
Refraction and liquid translucency
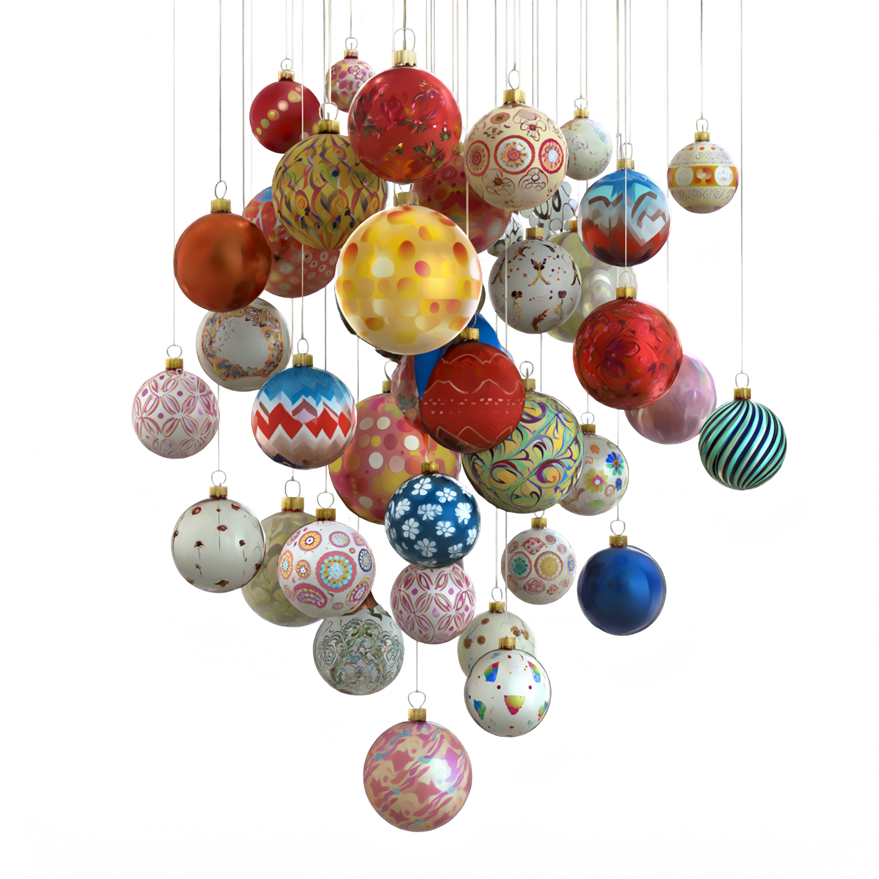
Composite Transparency: Tech HUD Module
Layered multi-element alpha

Composite Transparency: 3D Typography Badge
Embossed dimensional typography

Expression Edit on Transparent Asset
Modify facial expression while keeping transparency

Text Edit on Transparent Ribbon
Replace text with matching typography
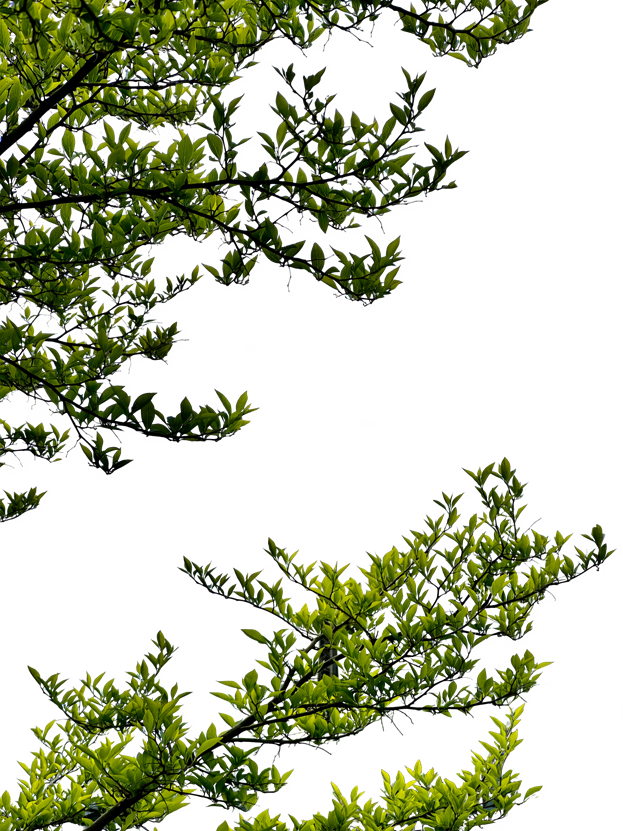
Photo to Transparent Layer Extraction
Extract RGBA layer from real photo
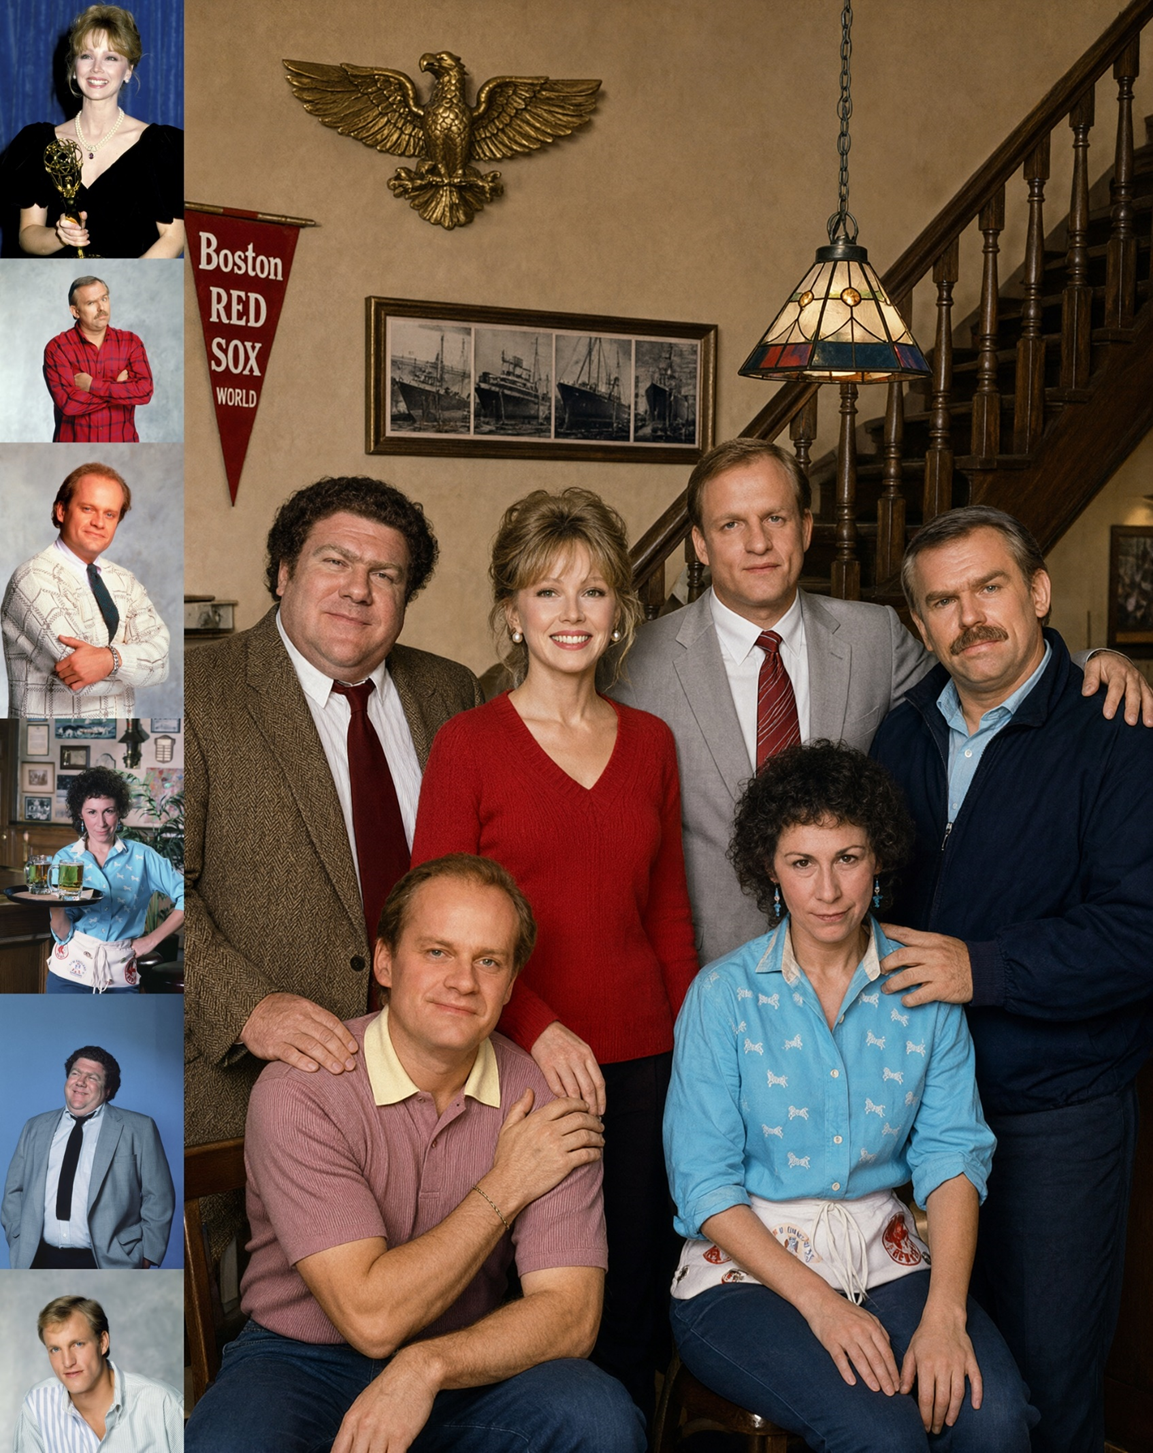
6-Person Group Photograph
Unified group composition from 6 face references
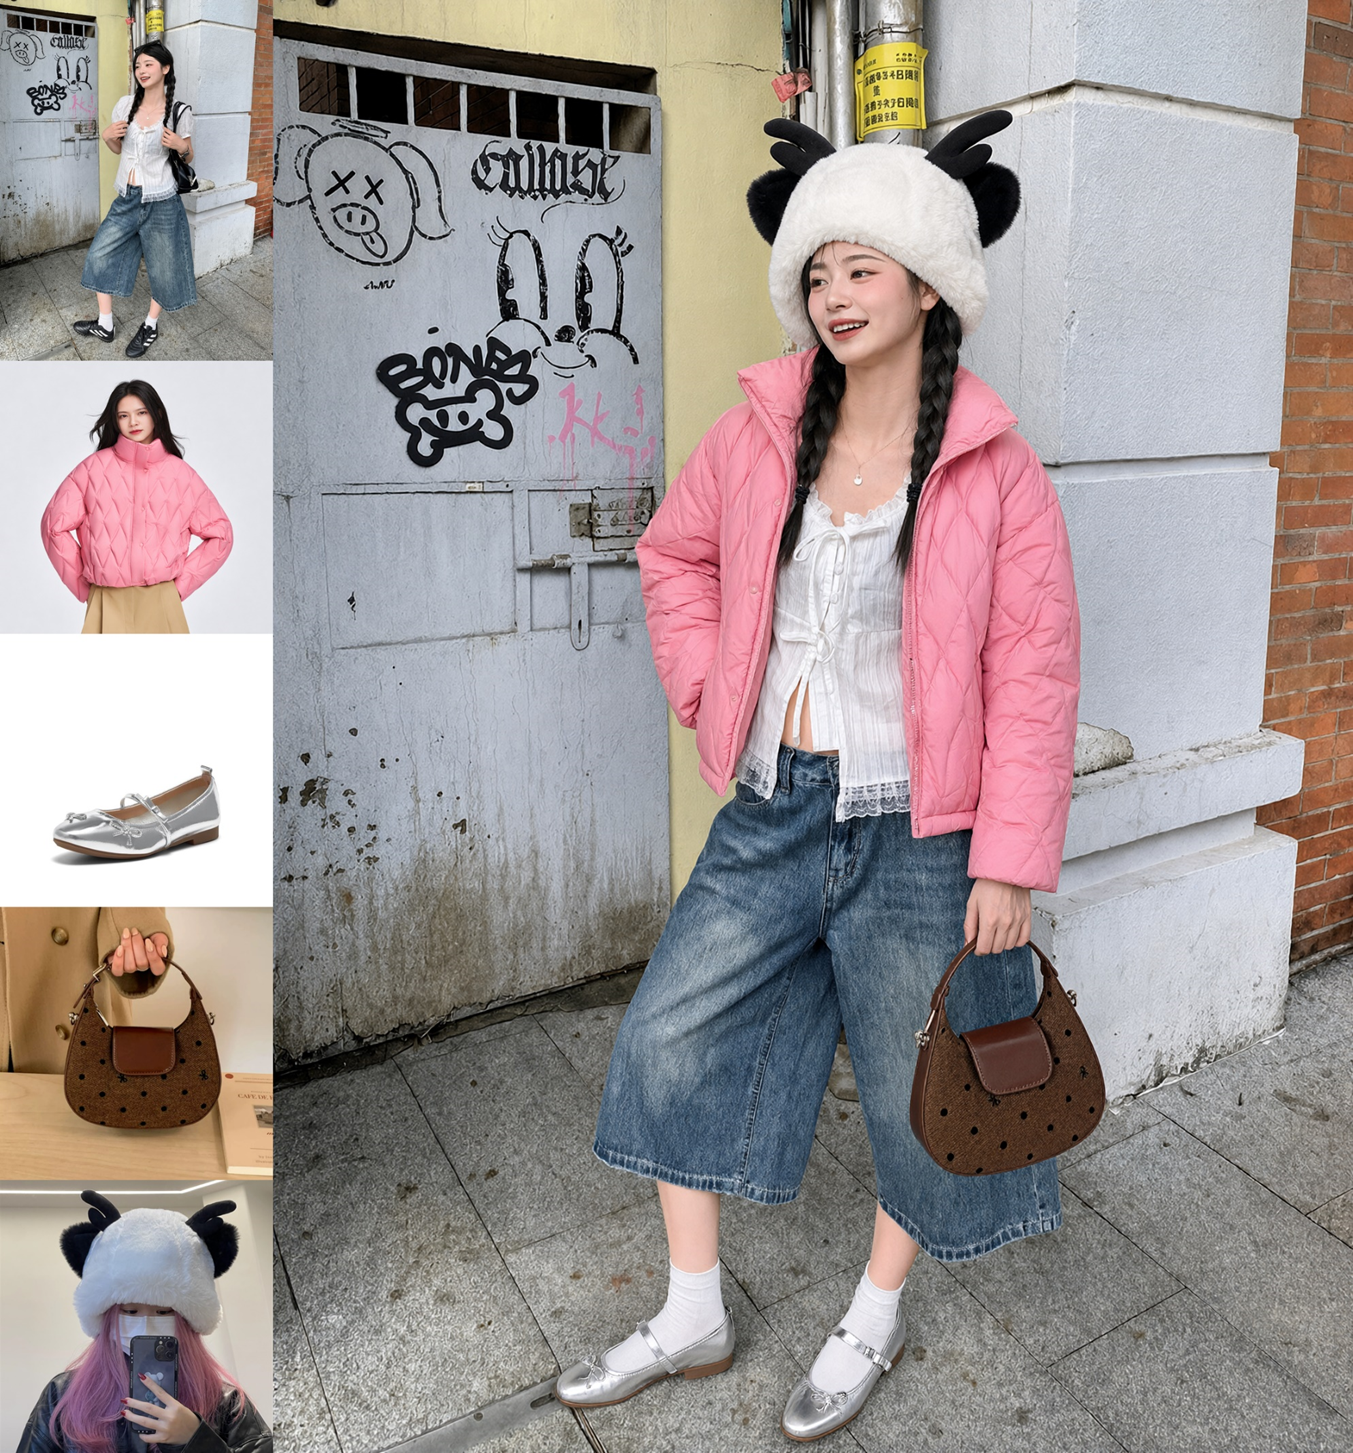
5-Asset Virtual Try-On
Model + top + pants + shoes + bag
10-Item Interior Layout
Harmonized 3D space with 10 reference objects
3-Color Inpainting Result
Simultaneous watch removal, hair recoloring, and pajama swap
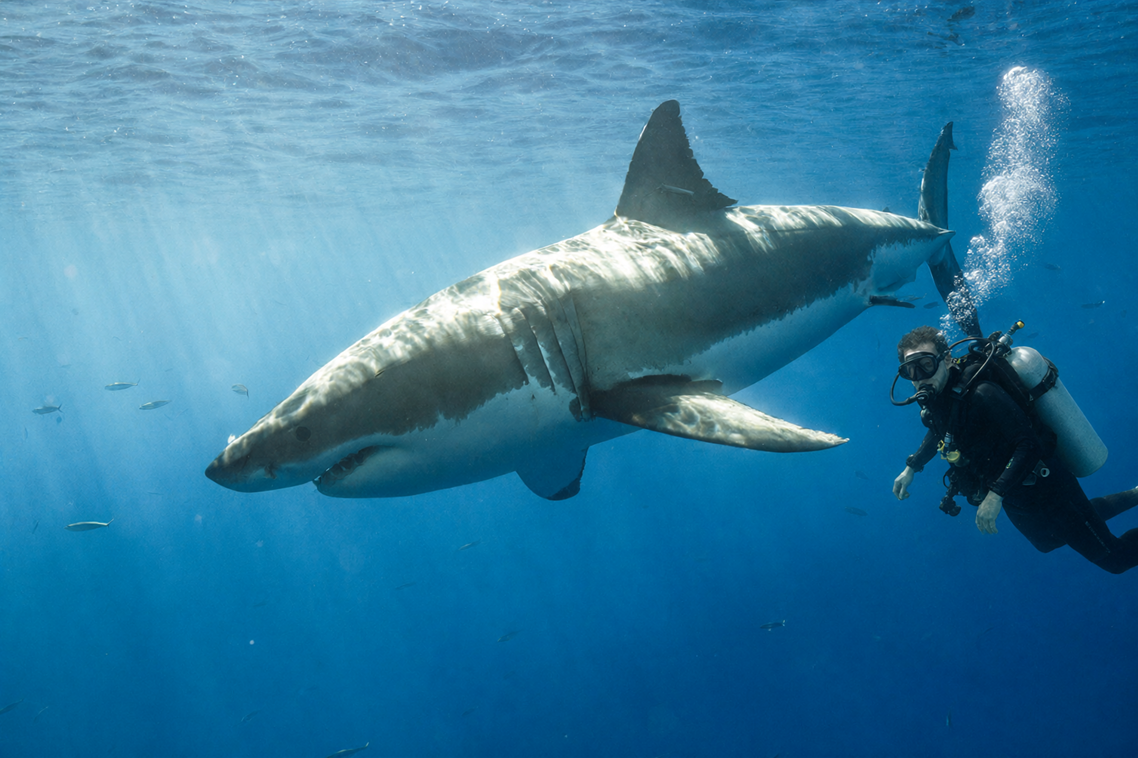
Painted Region: Submerged Diver
Seamless diver blend with aquatic caustics
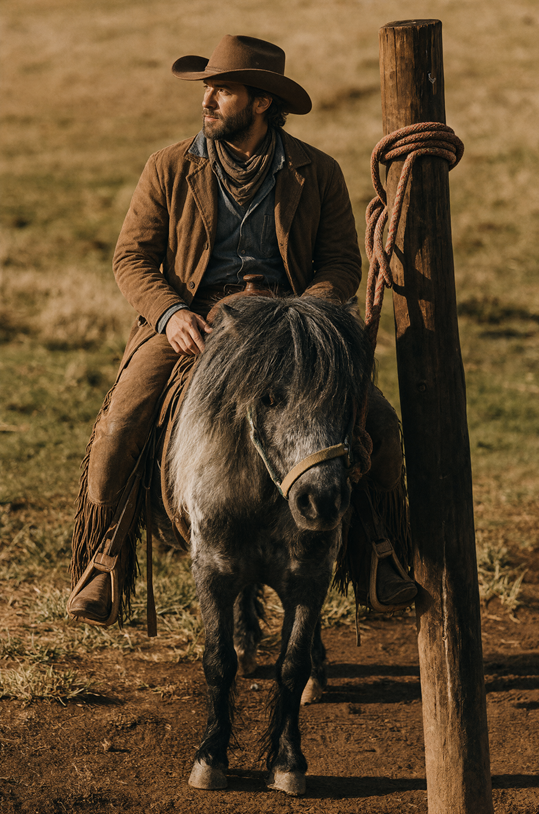
Mask Guided: Cowboy on Horseback
Untouched landscape pixels remain unchanged
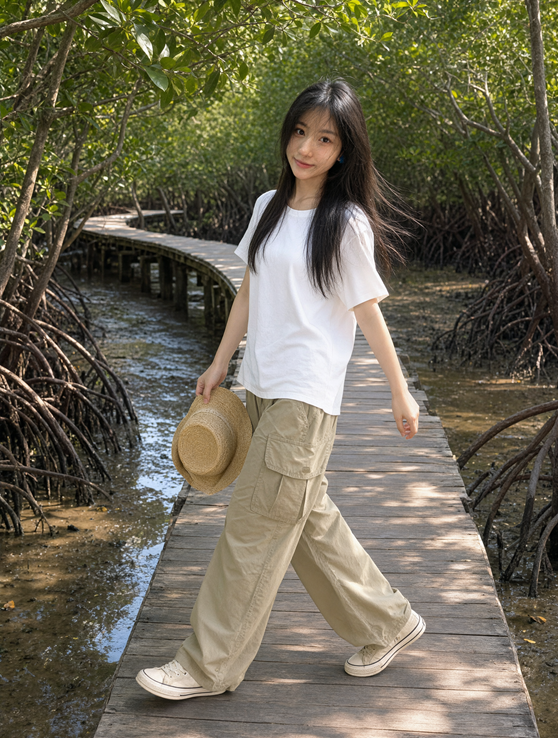
Portrait Identity Preservation (1)
Exact facial features and gaze retention
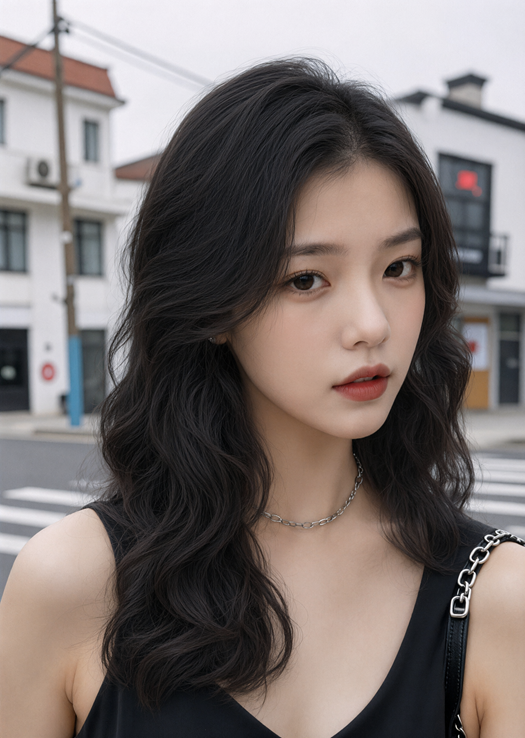
Portrait Identity Preservation (2)
Changed setting without losing facial identity
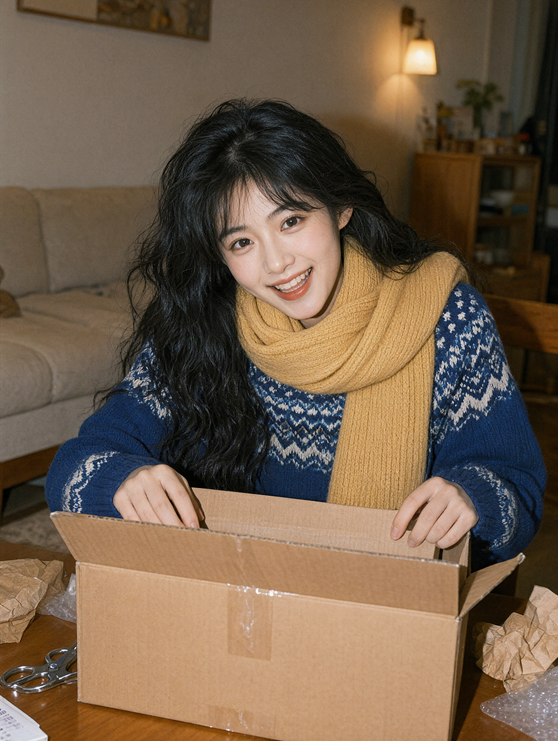
Portrait Identity Preservation (3)
Robust identity retention under dramatic lighting
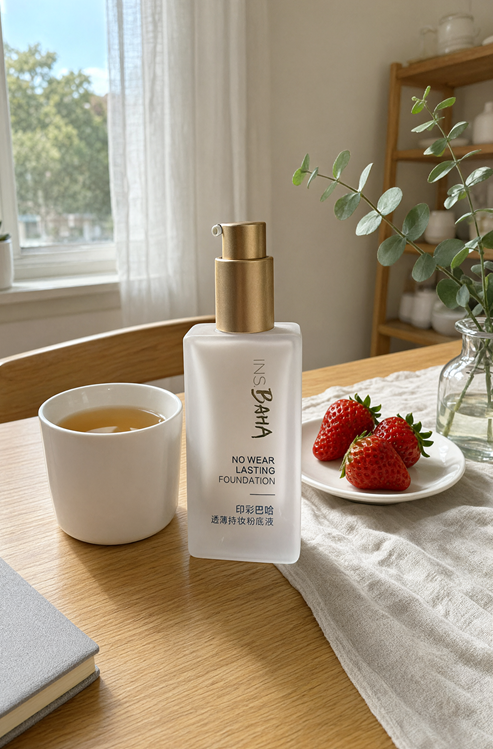
Product Fidelity: Leather Handbag
Preserved leather grain and metal hardware
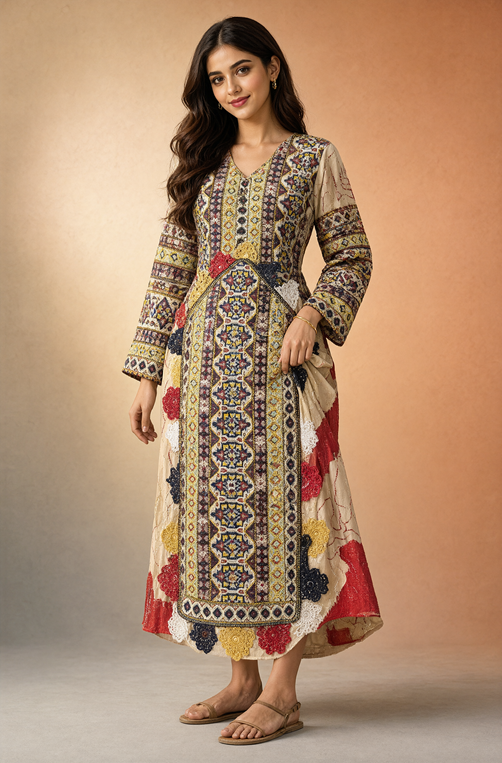
Product Fidelity: Perfume Bottle
Exact typography and glass thickness consistency
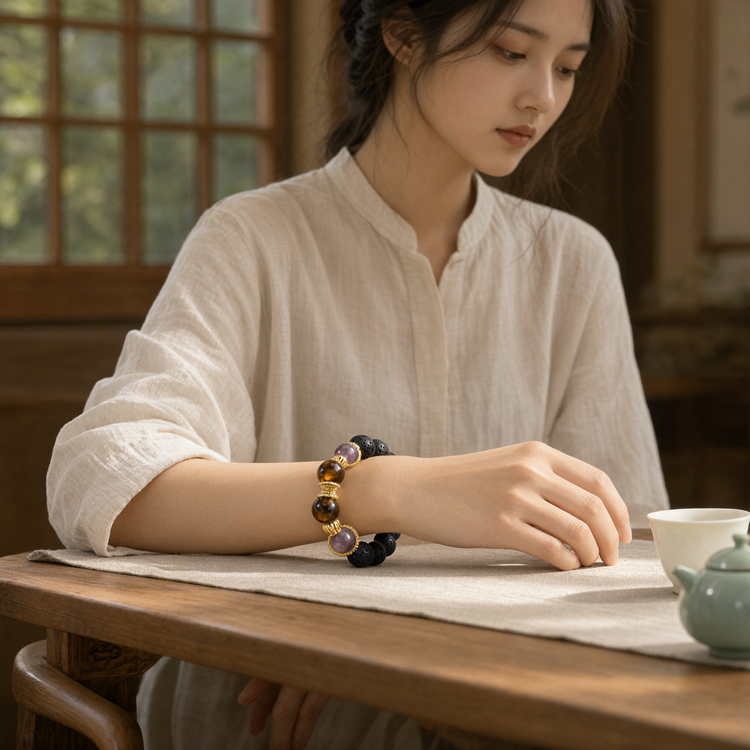
Product Fidelity: Footwear Geometry
No drift in sneaker color blocking and tread
Equirectangular 360° Panorama Sheet
Full panoramic environment extruded from selfie
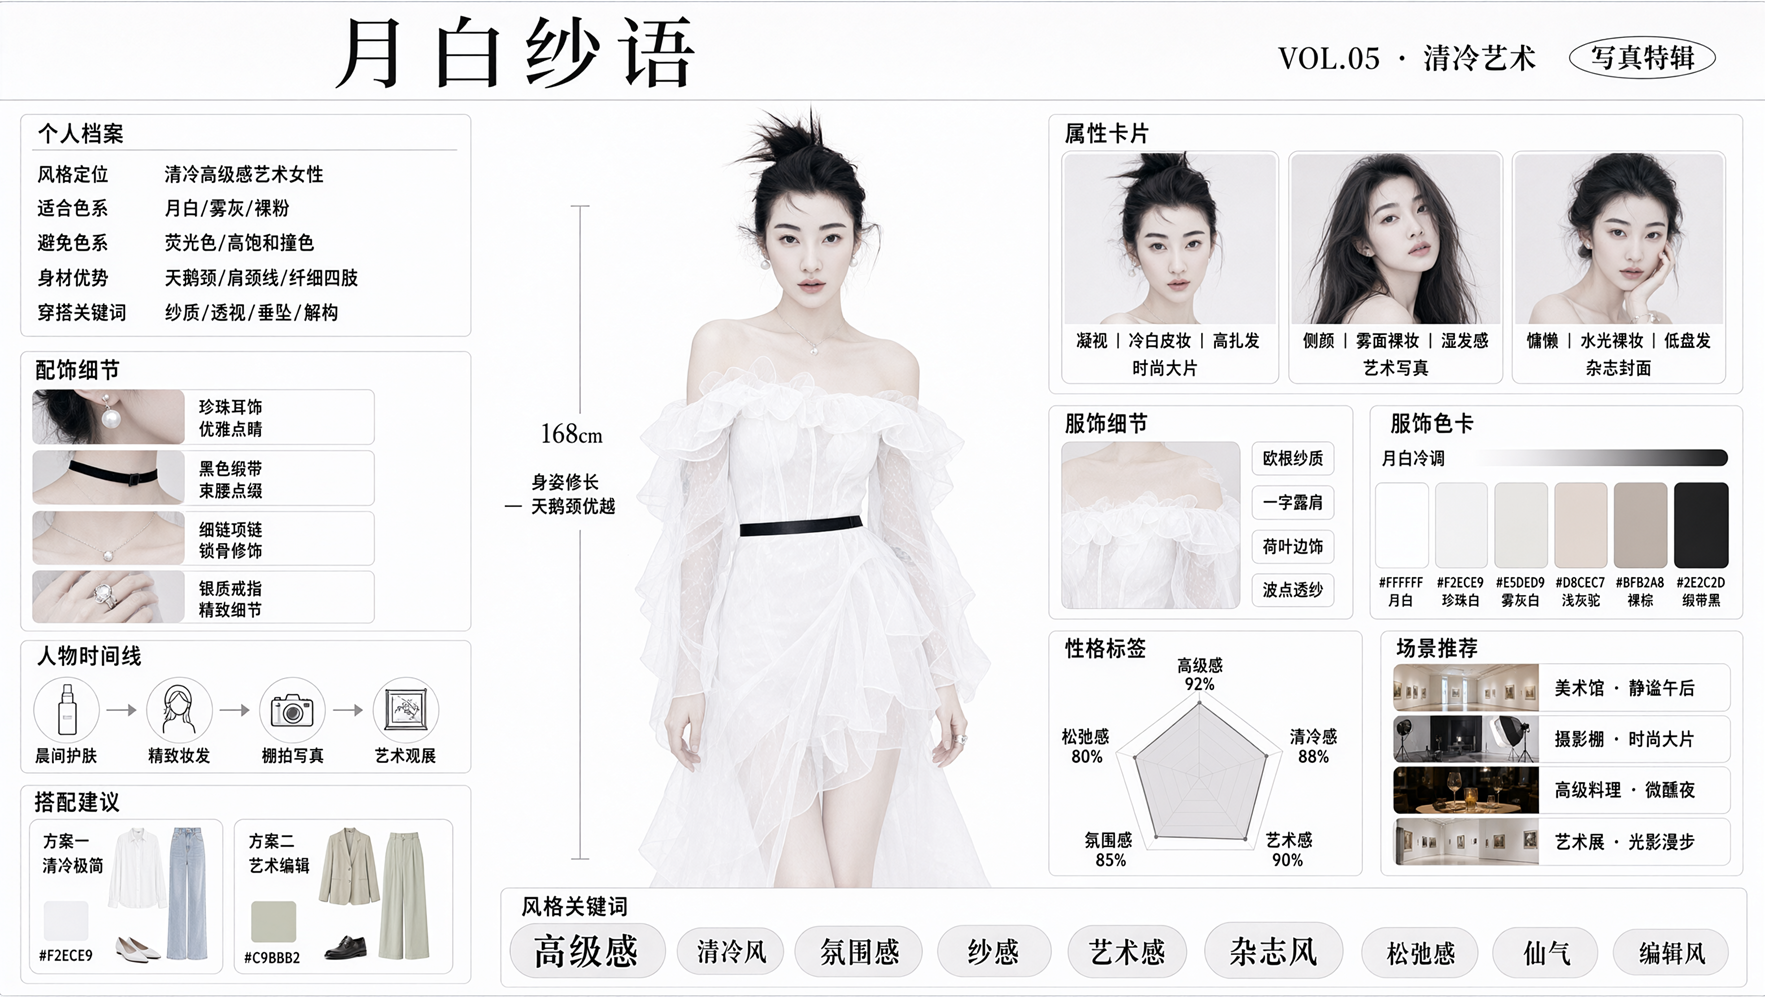
Dense Infographic Composition
Complex graphical multi-panel layout
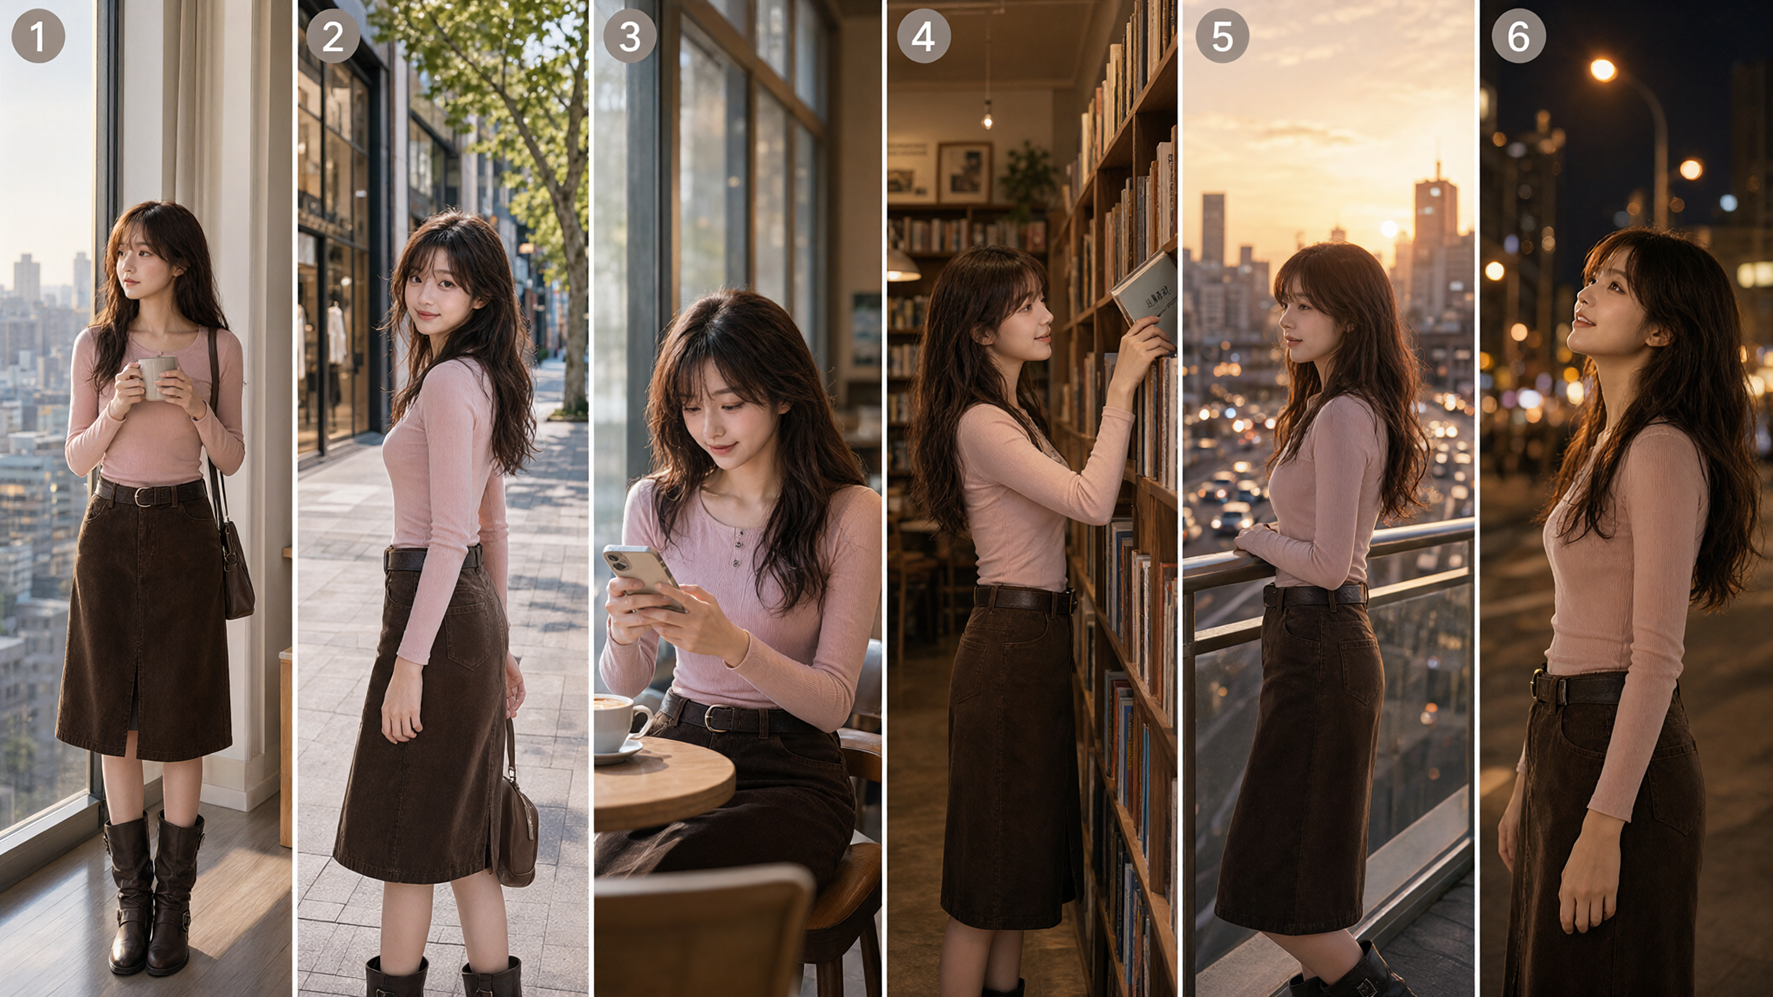
9-Panel Character Storyboard
Cinematic framing with ironclad consistency
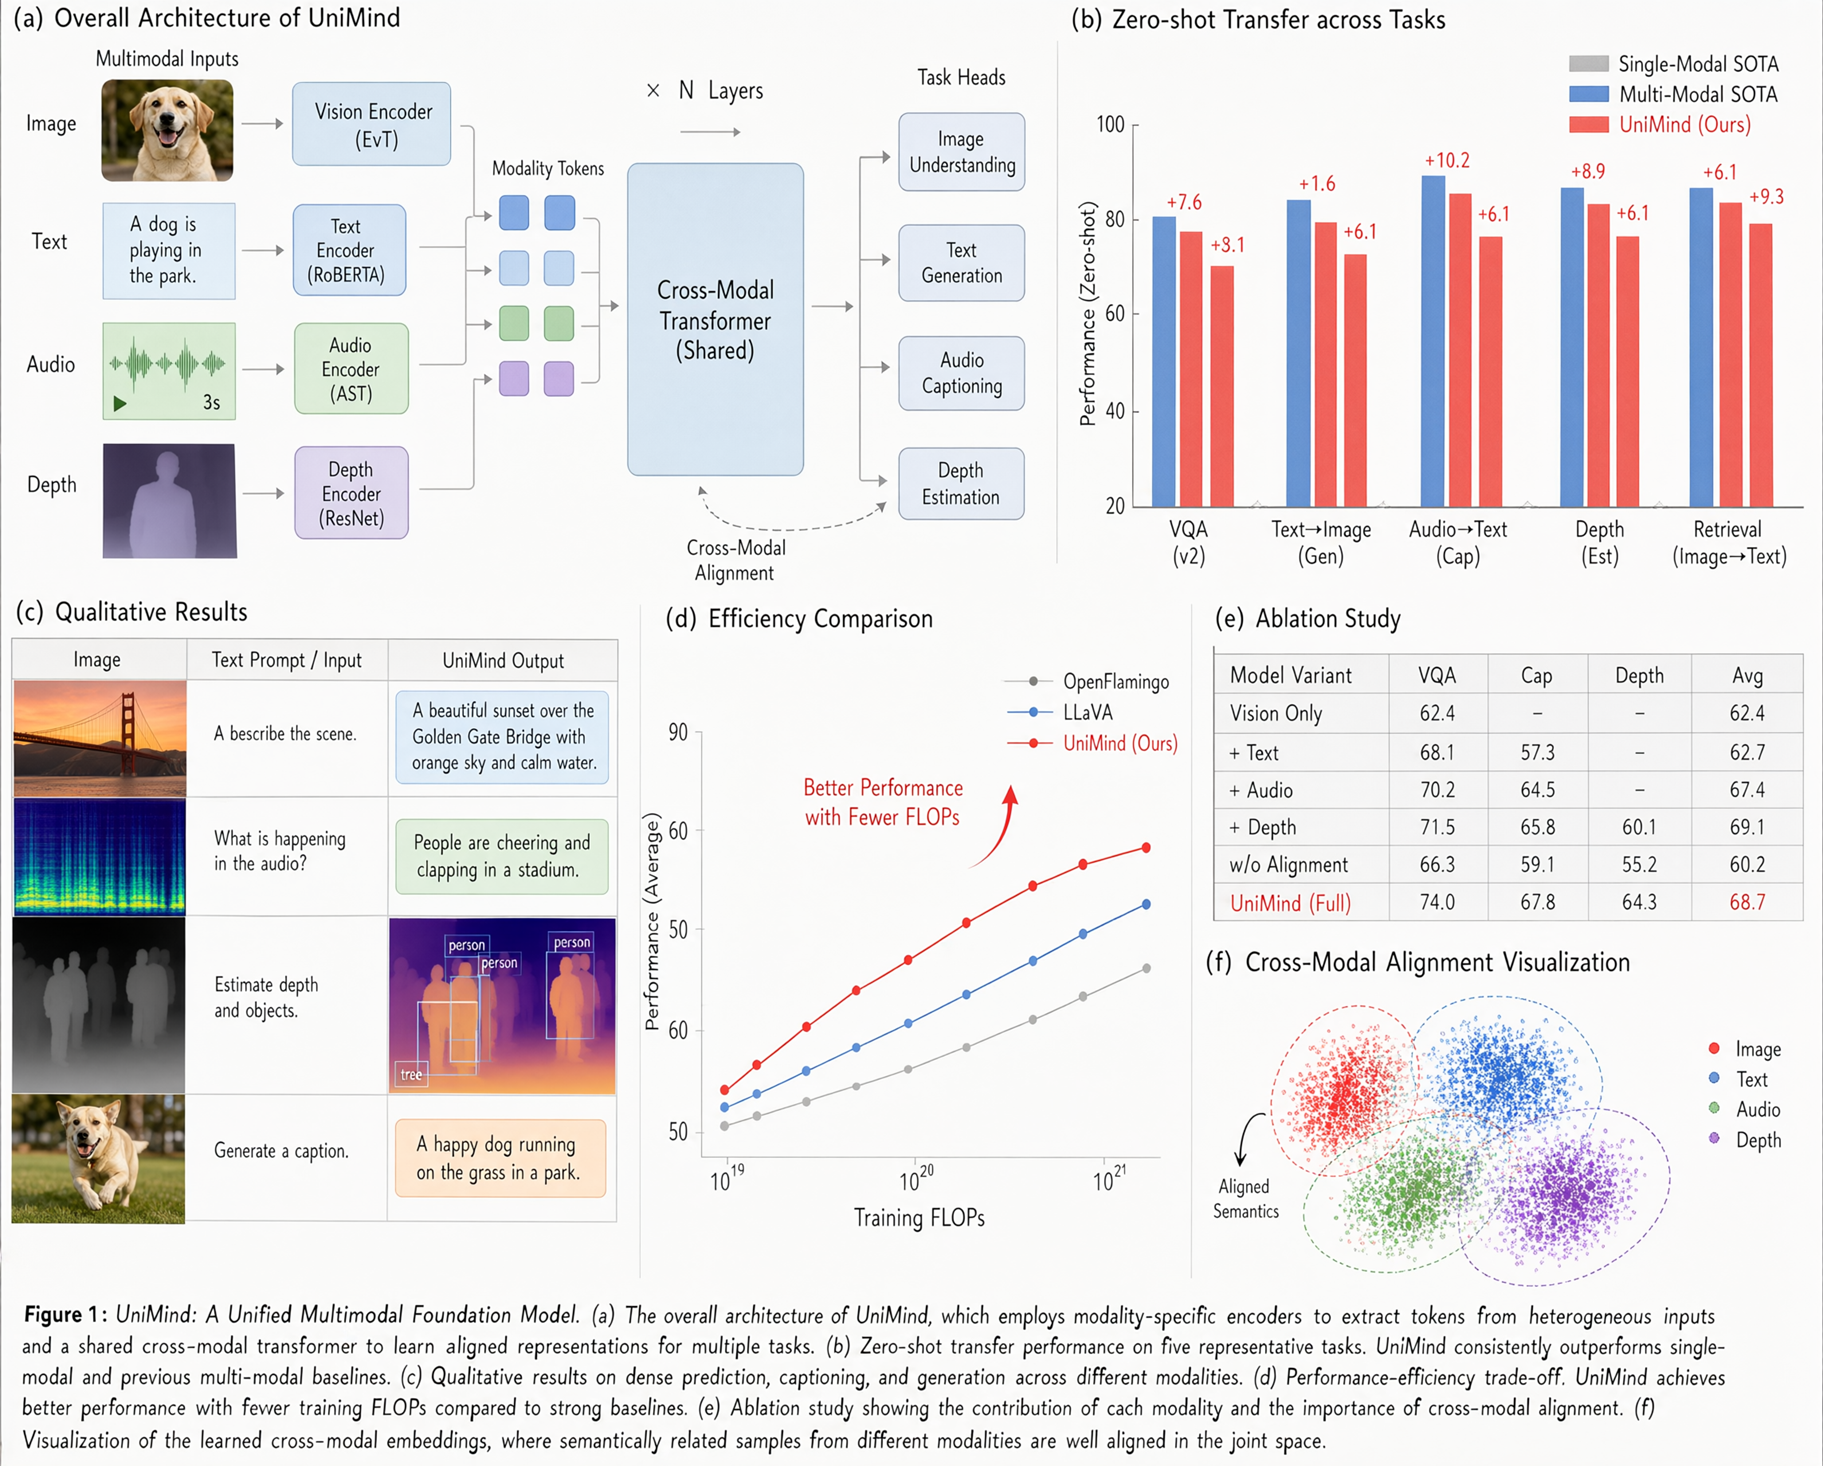
Typography Showcase 1: Vintage Jazz Poster
Flawless kerning and geometric layout hierarchy
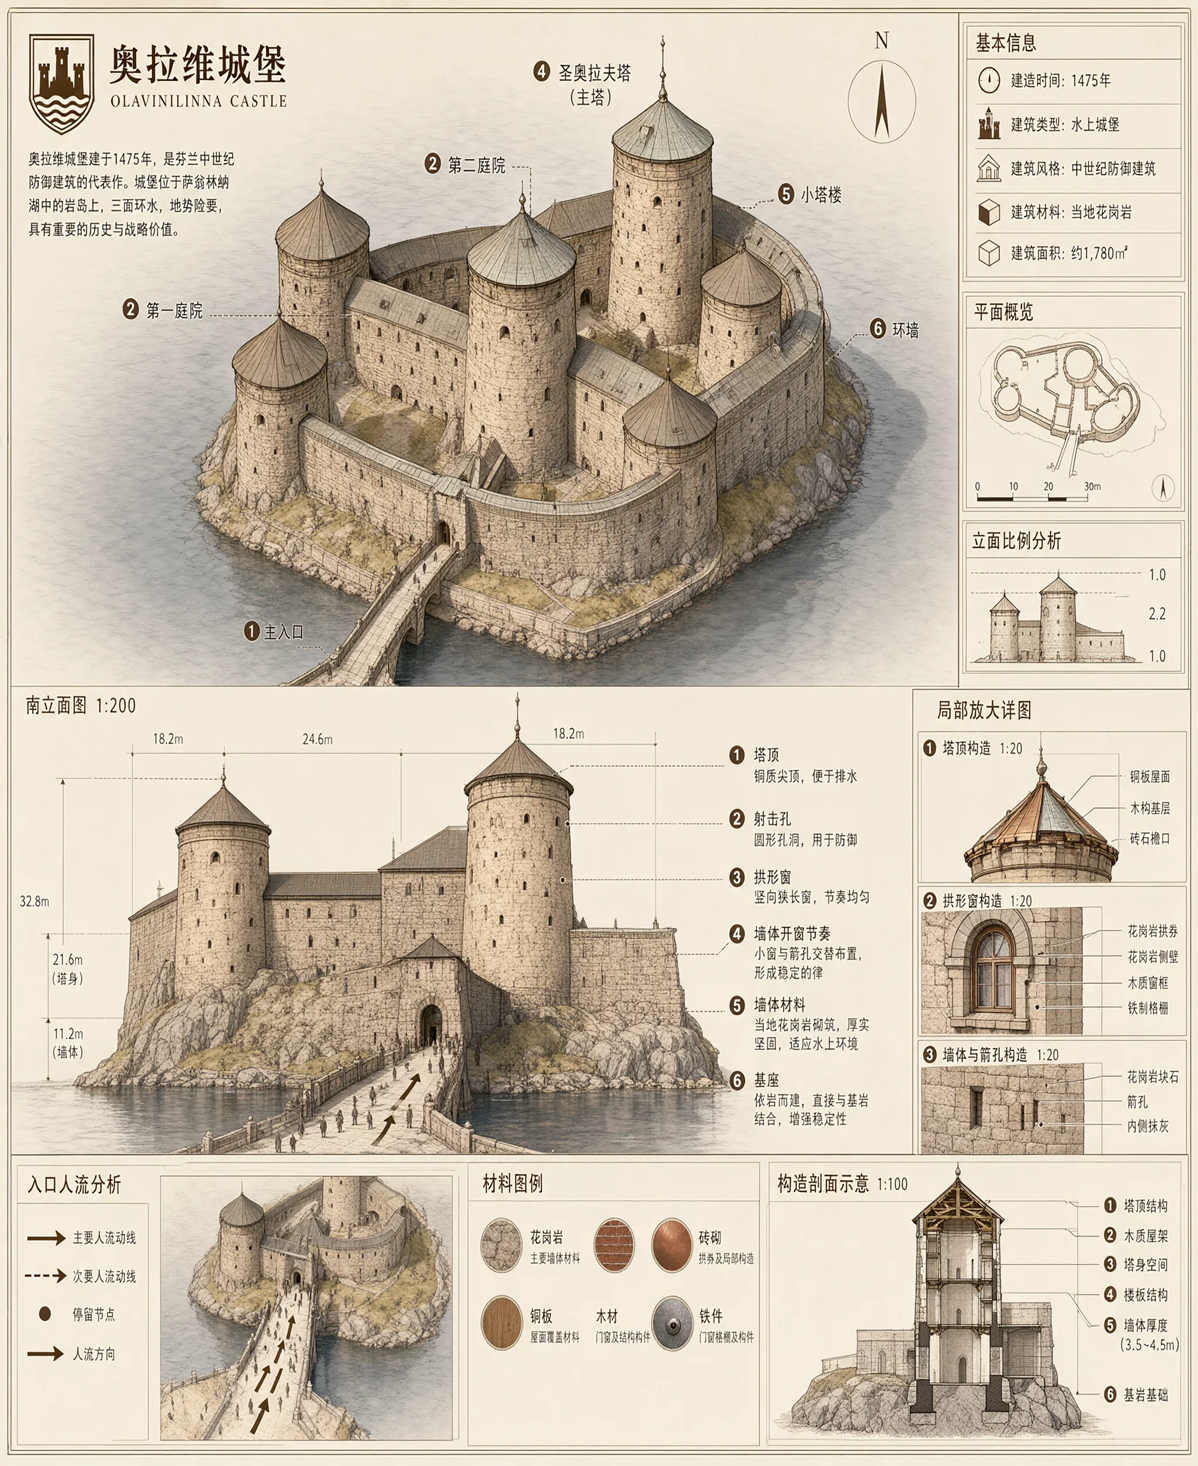
Typography Showcase 2: Modern Editorial Magazine
Clean headline typography with disciplined whitespace
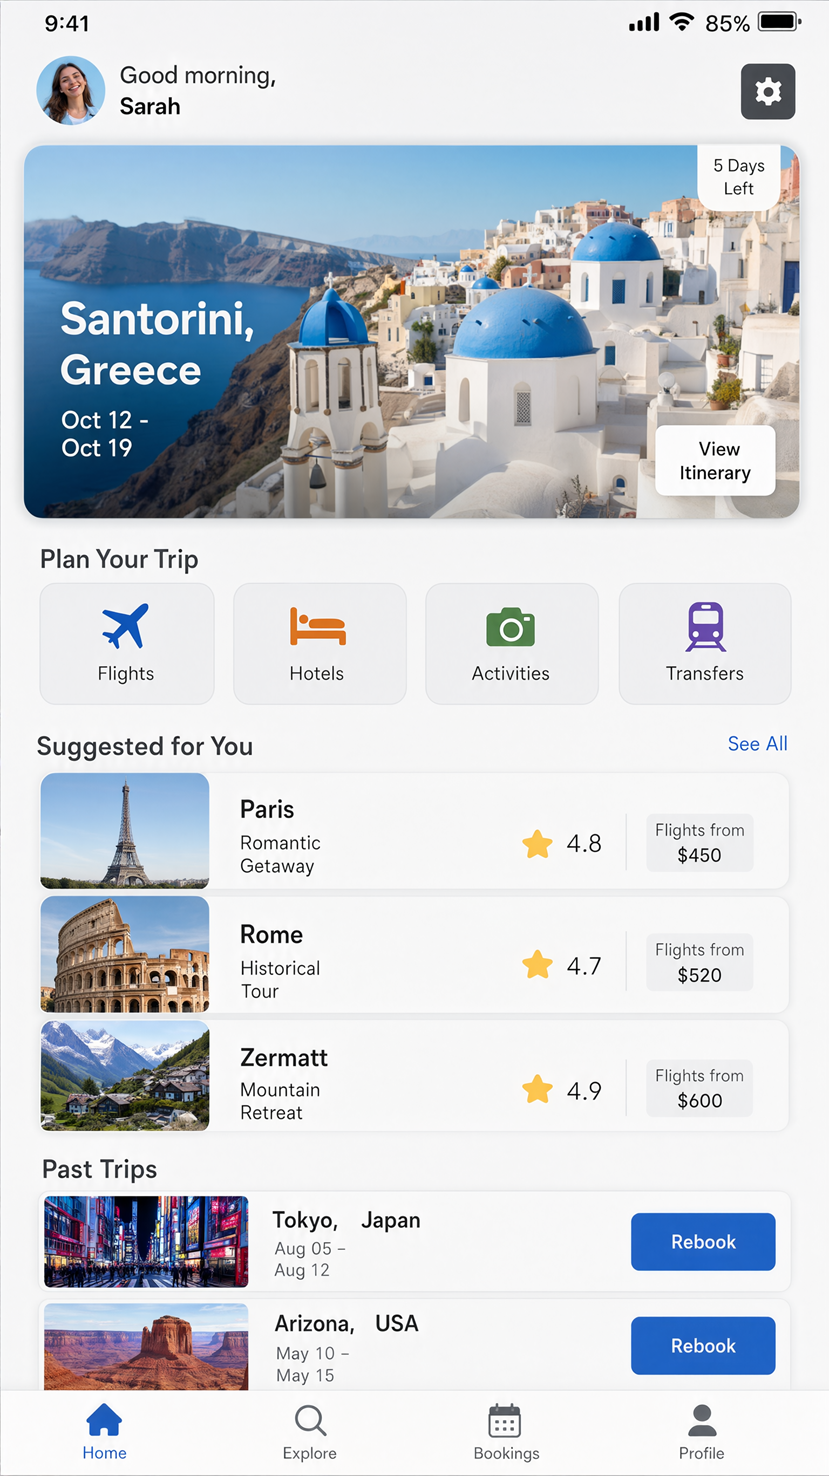
Typography Showcase 3: Cyberpunk Neon Signage
Neon signage with authentic luminescence
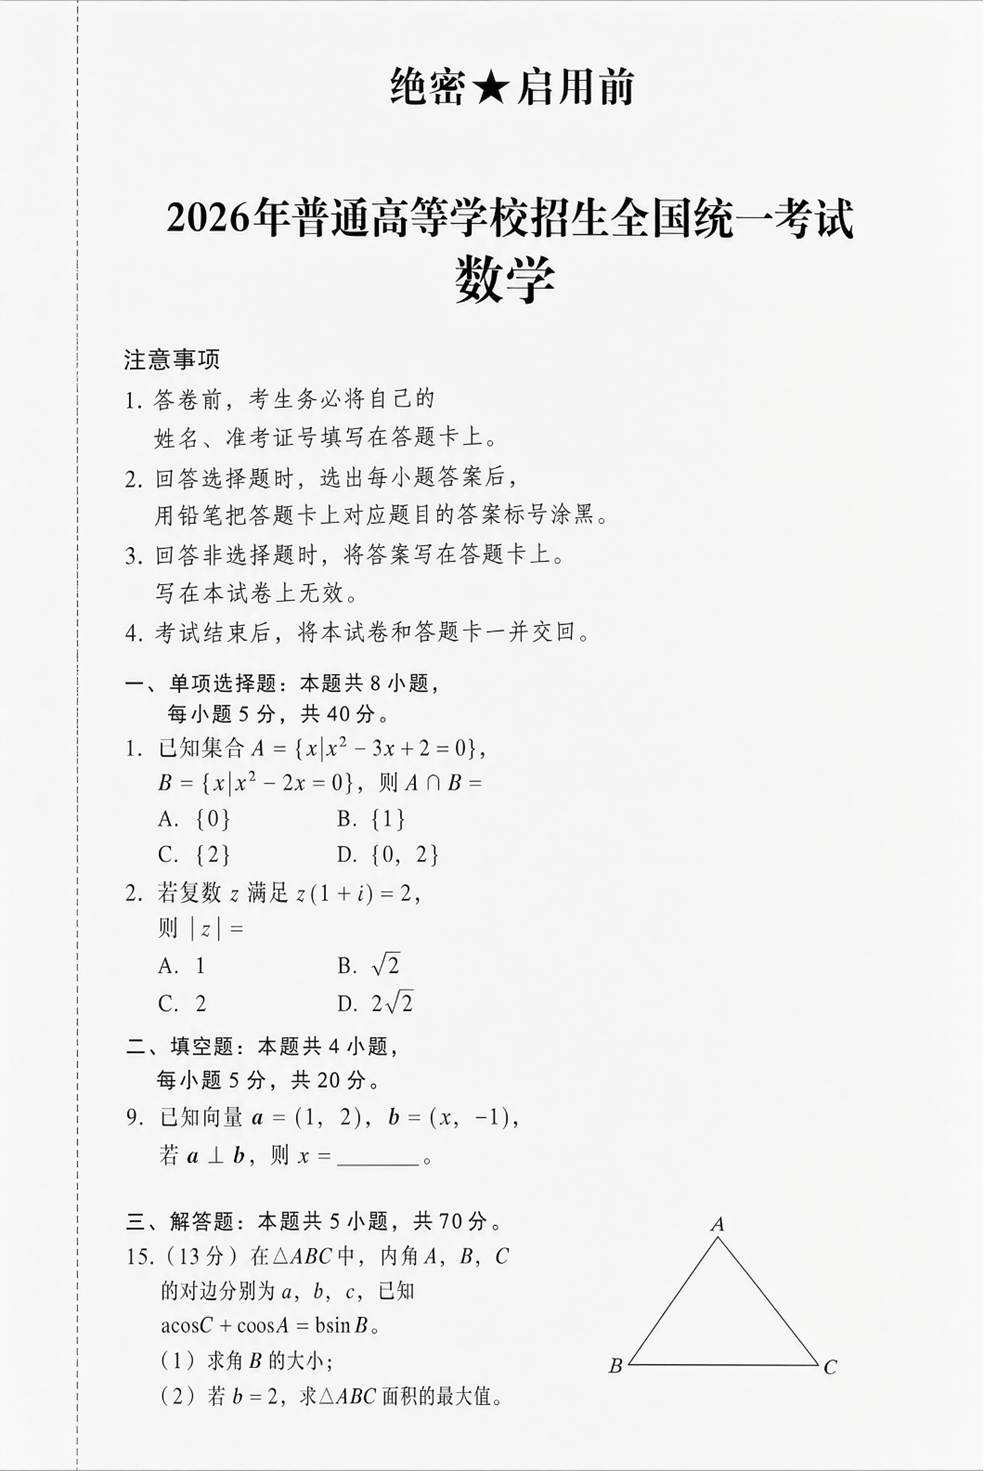
Typography Showcase 4: Artisan Coffee Packaging
Micro-typography and copperplate calligraphy
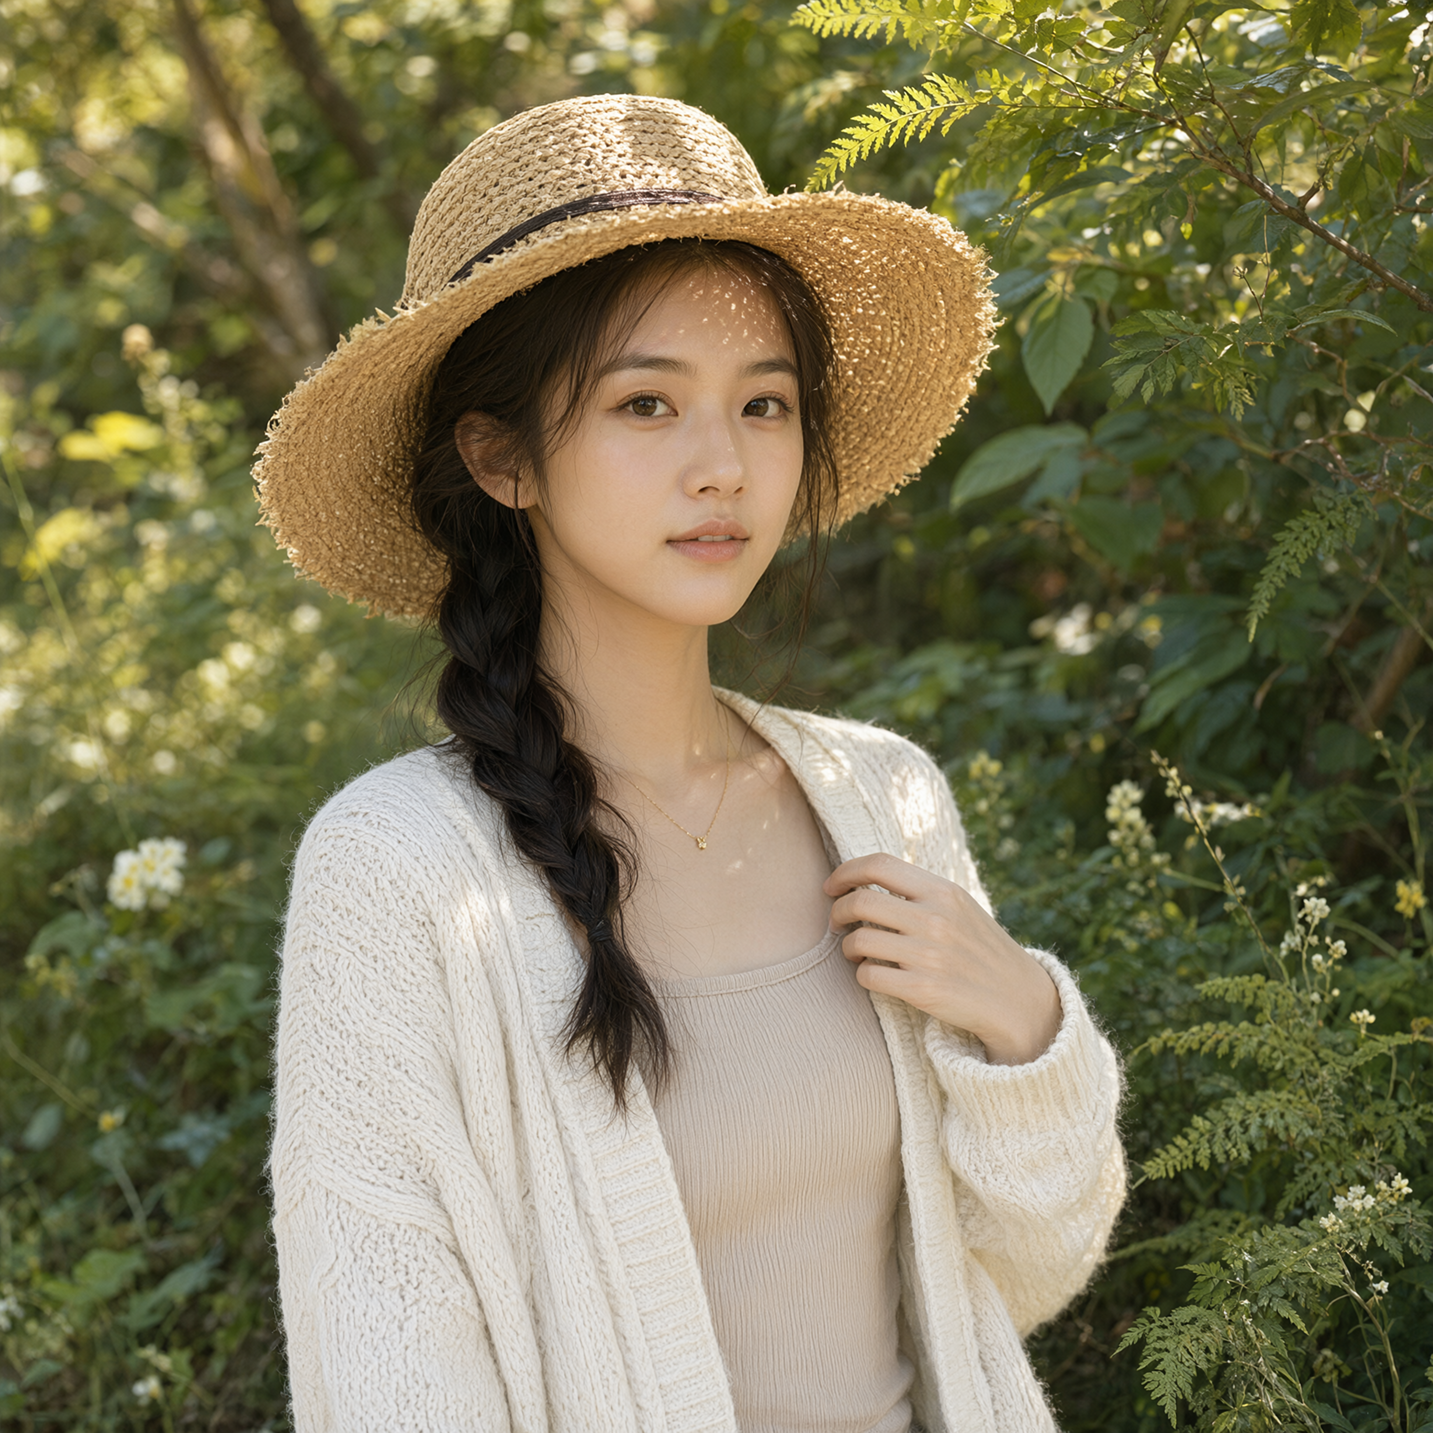
Portrait Realism 1: Natural Sunlight & Skin Texture
Subsurface scattering and natural non-plastic skin texture
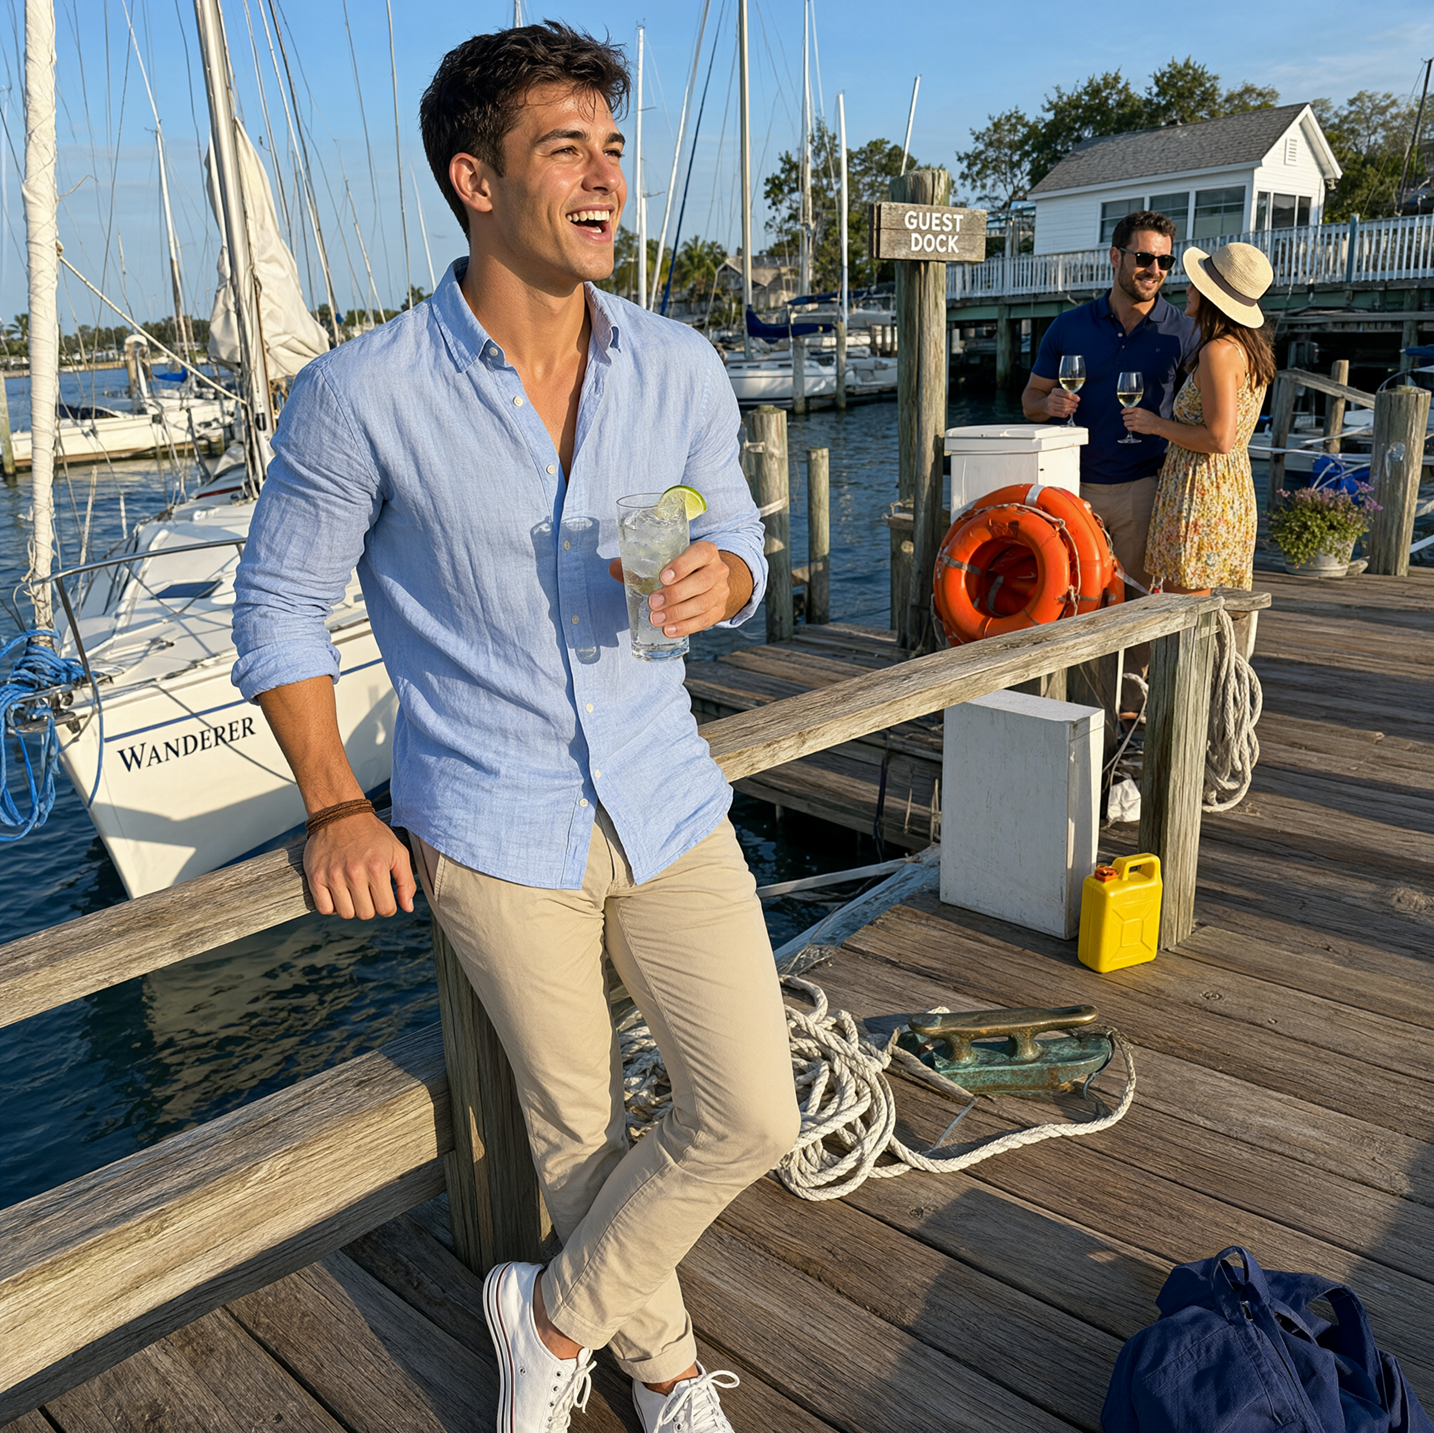
Portrait Realism 2: Studio Softbox & Expression
Expressive gaze catchlights and tactile fabric weave
8. Quick Start: Hugging Face & Python Inference
Qwen-Image-2.1 is fully open-sourced on Hugging Face and ModelScope. Below is a complete Python snippet for synthesizing direct RGBA transparent images:
import torch
from diffusers import QwenImagePipeline

# 加载 Qwen-Image-2.1 7B 官方开源权重 (Bfloat16 精度)
pipe = QwenImagePipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1",
    torch_dtype=torch.bfloat16,
    device_map="auto"
)

# 提示词中明确指定透明通道生成 (pure alpha transparency)
prompt = (
    "A mythical crystalline wyvern dragon with translucent iridescent wings, "
    "hovering mid-air, emitting subtle bioluminescence, pure alpha transparency background, "
    "extremely sharp edges without fringe, ultra photorealistic, 8k resolution, cinematic lighting."
)

# 执行单步扩散生成 (直接产出 RGBA 4 通道图像)
image = pipe(
    prompt=prompt,
    num_inference_steps=30,
    guidance_scale=4.5,
    output_type="pil"
).images[0]

# 保存为支持无损透明通道的 PNG 格式
image.save("qwen_crystal_dragon_transparent.png", format="PNG")
print("✅ Direct RGBA transparent image successfully saved!")9. Conclusion: A New Milestone for Open-Source Creativity
Qwen-Image-2.1 demonstrates that a compact 7B Single-Stream DiT can stand shoulder-to-shoulder with monolithic commercial flagships. By unifying direct RGBA layer generation, up to 10 reference inputs, and precision inpainting, it bridges the gap to industrial-grade design.
Whether you are constructing automated e-commerce workflows, generating storyboards from character turnarounds, or experimenting with zero-fringe transparent layers, Qwen-Image-2.1 is an essential addition to your creative toolbox.